
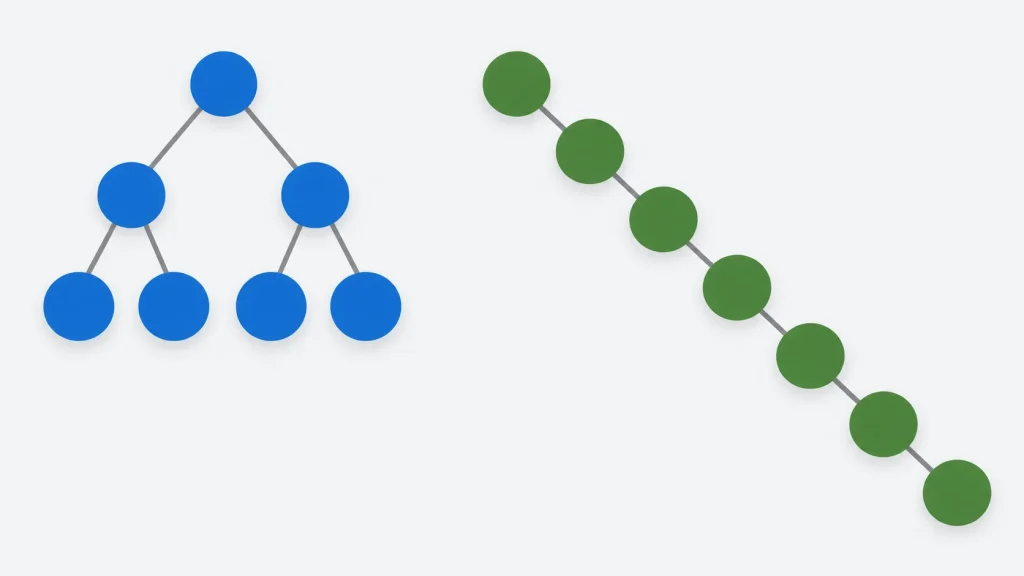
Insert the numbers 0 to 19,999 into a binary search tree in a shuffled order and, in this test, the tree was 30 levels deep. Insert the same numbers in sorted order and it is 19,999 levels deep: a linked list with an unused pointer in every node, which took 130 to 190 times as long to build. On that shape, a recursive height function ran out of call stack at about 261,000 levels when built with Clang and 627,000 with GCC, and Python’s default recursion limit stopped it at about 1,000. The usual description of a binary search tree as an O(log n) structure holds only for some insertion orders, and the code that walks it decides whether a deep tree is slow or fatal.
This guide defines binary trees and binary search trees, implements insert, search, removal and all four traversals in C, and measures how insertion order shapes the tree against the expected depth of a random tree. It then gives versions in C++, Java, Python and C#, and five mistakes that compile. Every program was compiled and run for this article on Ubuntu 24.04: C with GCC 13.3 and Clang 18.1.3 (-std=c11 and -std=c17) and C++ with g++ 13.3 and clang++ 18.1.3 (-std=c++17 and -std=c++20), all with -Wall -Wextra -pedantic and no warnings except where a mistake shows one; Java on OpenJDK 21, Python 3.13 (also checked with ruff and mypy --strict), and C# on .NET 10 with analyzer warnings as errors. All five build the same tree and print the same output. The C and C++ tests also ran clean under AddressSanitizer and UndefinedBehaviorSanitizer, and the code is in five GitHub repositories whose builds run the tests on each change to the example.
What Is a Binary Tree?
A binary tree is a set of nodes in which each node holds a value and links to at most two children, called left and right. One node, the root, has no parent; every other node has exactly one. A binary search tree adds an ordering rule: every key in a node’s left subtree is smaller than the node’s key, and every key in its right subtree is larger.
The vocabulary is short. A node with no children is a leaf. The depth of a node is the number of edges from the root down to it, so the root has depth 0. The height of a tree is the depth of its deepest node: 0 for a single node, and −1 by convention for an empty tree. Some books count nodes instead of edges, which adds one to every height; this article counts edges throughout. A subtree is any node together with everything below it, which is why most tree algorithms are naturally recursive: the left and right children of a node are themselves the roots of smaller binary trees.
A few shapes have names, and they matter because the cost of most operations is the height:
| Shape | Definition | Height for n nodes |
|---|---|---|
| Full | Every node has zero or two children | Anywhere from about log₂ n to (n − 1) / 2 |
| Complete | Every level is filled except possibly the last, which fills from the left | ⌊log₂ n⌋ |
| Perfect | Every level is completely filled | log₂(n + 1) − 1 |
| Degenerate | Every node has at most one child | n − 1 |
A complete binary tree is the shape a binary heap uses, and it fits in an array with no pointers at all: the children of the node at index i sit at 2i + 1 and 2i + 2. The heap sort article builds one. Everything else on this page uses linked nodes, which can take any shape, and a binary search tree, which uses the ordering rule to find a key without looking at most of the nodes. C++’s std::set is a binary search tree too, of a self-balancing kind; it appears later as the yardstick.
A Binary Search Tree in C
Each node is a structure with a key and two pointers, the linked list node with one more link. Insertion and search walk down from the root, going left when the key is smaller and right when it is larger:
#include <stdbool.h>
#include <stddef.h>
#include <stdint.h>
#include <stdio.h>
#include <stdlib.h>

typedef struct Node {
    int          key;
    struct Node *left;    /* keys smaller than key */
    struct Node *right;   /* keys larger than key  */
} Node;

typedef void (*Visit)(int key, void *ctx);

/* Returns 1 if inserted, 0 if the key was already present, -1 if malloc failed. */
int bst_insert(Node **root, int key)
{
    Node **link = root;                     /* the pointer that will hold the node */
    while (*link != NULL) {
        if (key < (*link)->key)
            link = &(*link)->left;
        else if (key > (*link)->key)
            link = &(*link)->right;
        else
            return 0;
    }
    Node *n = malloc(sizeof *n);
    if (n == NULL)
        return -1;
    n->key = key;
    n->left = n->right = NULL;
    *link = n;                              /* writes into the parent, or into *root */
    return 1;
}

bool bst_contains(const Node *root, int key)
{
    while (root != NULL) {
        if (key < root->key)
            root = root->left;
        else if (key > root->key)
            root = root->right;
        else
            return true;
    }
    return false;
}
bst_insert takes Node **root, a pointer to the caller’s root pointer, and walks link down the tree as the address of whichever pointer the new node must be stored in. When the loop stops, *link is the empty slot: the caller’s root for the first insertion, or a parent’s left or right field after that. One assignment covers every case, and no parent pointer or special case for the root is needed. Passing the root by value instead is the first of the mistakes later in the article.
Both functions use a loop rather than recursion, so their cost is one step per level and they use no extra stack however deep the tree is. Keys are unique: inserting one that is already present returns 0 and leaves the tree unchanged. The return value also separates “already there” from “out of memory”, which a bool could not.
Tree Traversals: Preorder, Inorder, Postorder and Level Order
A traversal visits every node once. The three depth-first orders differ only in when a node is visited relative to its two subtrees, and the fourth goes level by level:
The depth-first orders are three lines each when written recursively. Visit is a callback, so the same traversal can print, count or collect:
/* Recursive depth-first traversals: one stack frame per level. */
void bst_preorder(const Node *t, Visit visit, void *ctx)
{
    if (t == NULL)
        return;
    visit(t->key, ctx);
    bst_preorder(t->left, visit, ctx);
    bst_preorder(t->right, visit, ctx);
}

void bst_inorder(const Node *t, Visit visit, void *ctx)
{
    if (t == NULL)
        return;
    bst_inorder(t->left, visit, ctx);
    visit(t->key, ctx);
    bst_inorder(t->right, visit, ctx);
}

void bst_postorder(const Node *t, Visit visit, void *ctx)
{
    if (t == NULL)
        return;
    bst_postorder(t->left, visit, ctx);
    bst_postorder(t->right, visit, ctx);
    visit(t->key, ctx);
}
Each call takes one stack frame, and the calls nest as deep as the tree is high. For a balanced tree of a million keys that is about 20 frames; for the chain that sorted insertion builds, it is a million, which is where the crash in the introduction comes from. An explicit stack moves that memory from the call stack to the heap. The in-order walk below pushes the path to the leftmost node, visits it, and continues from its right child; the level-order walk uses the same array as a queue:
/* A growable array of node pointers, used as a stack or a queue. */
typedef struct {
    const Node **items;
    size_t       len, cap;
} NodeVec;

static bool vec_push(NodeVec *v, const Node *n)
{
    if (v->len == v->cap) {
        size_t cap = v->cap ? v->cap * 2 : 16;
        if (cap > SIZE_MAX / sizeof *v->items)
            return false;
        const Node **p = realloc(v->items, cap * sizeof *v->items);
        if (p == NULL)
            return false;
        v->items = p;
        v->cap = cap;
    }
    v->items[v->len++] = n;
    return true;
}

/* In-order with an explicit stack: the stack grows on the heap, not the call
 * stack. Returns false if it could not allocate; some keys may have been
 * visited by then. */
bool bst_inorder_iter(const Node *t, Visit visit, void *ctx)
{
    NodeVec stack = {0};
    bool ok = true;
    while (ok && (t != NULL || stack.len > 0)) {
        if (t != NULL) {
            ok = vec_push(&stack, t);       /* go left, remembering the path */
            t = t->left;
        } else {
            t = stack.items[--stack.len];
            visit(t->key, ctx);
            t = t->right;
        }
    }
    free(stack.items);
    return ok;
}

/* Breadth-first: level by level, left to right, with a queue. */
bool bst_level_order(const Node *t, Visit visit, void *ctx)
{
    NodeVec queue = {0};
    size_t head = 0;
    bool ok = t == NULL || vec_push(&queue, t);
    while (ok && head < queue.len) {
        const Node *n = queue.items[head++];
        visit(n->key, ctx);
        if (n->left != NULL)
            ok = vec_push(&queue, n->left);
        if (ok && n->right != NULL)
            ok = vec_push(&queue, n->right);
    }
    free(queue.items);
    return ok;
}
The demo program inserts ten keys and prints all four orders, then removes three keys. Its output, identical under GCC and Clang:
Output:
inserted:    50 30 70 20 40 60 80 35 45 65
preorder:    50 30 20 40 35 45 70 60 65 80
inorder:     20 30 35 40 45 50 60 65 70 80
postorder:   20 35 45 40 30 65 60 80 70 50
level order: 50 30 70 20 40 60 80 35 45 65
size 10, height 3
contains 45: yes, contains 55: no
insert 40 again: 0

remove 30 (two children)
inorder:     20 35 40 45 50 60 65 70 80
level order: 50 35 70 20 40 60 80 45 65

remove 50 (root), 20 (leaf)
inorder:     35 40 45 60 65 70 80
level order: 60 35 70 40 65 80 45
size 7, height 3
remove 99: not found
In-order output of a binary search tree is the keys in sorted order, which is a quick check that the ordering rule holds after any change. Postorder visits a node after both of its subtrees, which is the order in which a tree must be freed: children before parents. Level order is breadth-first, and it is the only one of the four that needs a queue rather than a stack.
Removing a Node
Removal has three cases. A leaf is unlinked. A node with one child is replaced by that child. A node with two children cannot simply be unlinked, because its parent has room for only one of them, so the node takes the key of its in-order successor, the smallest key in its right subtree, and the successor is removed instead. The successor has no left child (it would be smaller), so removing it is one of the two easy cases:
/* Returns true if the key was found and removed. */
bool bst_remove(Node **root, int key)
{
    Node **link = root;
    while (*link != NULL && (*link)->key != key)
        link = key < (*link)->key ? &(*link)->left : &(*link)->right;
    Node *n = *link;
    if (n == NULL)
        return false;

    if (n->left == NULL) {
        *link = n->right;                   /* zero children or right child only */
    } else if (n->right == NULL) {
        *link = n->left;                    /* left child only */
    } else {
        /* Two children: the successor is the smallest key in the right subtree.
         * It has no left child, so it can be unlinked by replacing it with its
         * right child. Its key then takes the removed key's place. */
        Node **succ_link = &n->right;
        while ((*succ_link)->left != NULL)
            succ_link = &(*succ_link)->left;
        Node *succ = *succ_link;
        *succ_link = succ->right;
        n->key = succ->key;
        n = succ;                           /* the node to free */
    }
    free(n);
    return true;
}
The demo’s removals cover all three. Removing 30, which has two children, copies 35 up from the right subtree and unlinks the old 35 node: the second level-order line reads 50 35 70. Removing the root 50 copies 60 up and links 60’s right child, 65, into its place under 70. Removing the leaf 20 just clears a pointer. The test suite also removes a node with only a left child and one with only a right child, and checks after 200,000 random operations that the tree still matches a separate record of which keys are present.
How This Was Measured
| Setting | Value |
|---|---|
| Date tested | November 2026 |
| Hardware | Intel Xeon at 2.10 GHz, cloud VM, nproc reports 2; all code single-threaded |
| Operating system | Ubuntu 24.04, glibc 2.39, default 8 MiB stack (ulimit -s 8192) |
| Compilers | GCC 13.3 and Clang 18.1.3 at -O2; g++ 13.3 and clang++ 18.1.3 with libstdc++ 13 |
| Input | The keys 0 to n − 1, in sorted order or shuffled with a fixed-seed xorshift generator |
| Shape measurements | Height and mean node depth from a level-order walk; 1,000 trees at n = 1,000 down to 10 trees at n = 1,000,000 |
| What is timed | Building the tree (C), or building it and looking up every key (C++); timespec_get in C, std::chrono::steady_clock in C++ |
| Statistic | C: one build per run; C++: median of 5. Each program was run three times per compiler, and the text gives the range |
No CPU pinning or frequency control was used, and all timings come from one virtual machine, so the ratios are indications for this machine. The heights and depths do not depend on the machine: they are fixed by the keys and the generator, and they came out identical in all six runs.
Height, Depth and Why Insertion Order Matters
Search, insertion and removal all walk one path from the root, so each costs one step per level of the path: proportional to the height in the worst case and to the node’s depth on average. How deep the tree is depends entirely on the order the keys arrived in:
The shape program builds trees from shuffled and sorted keys and reports both measures:
Output (GCC, one of three runs):
random insertion order (keys 0..n-1, fixed-seed shuffles)
        n  trials  height range mean height      mean depth  predicted
     1000    1000         17-29        20.9          10.961     10.986
    10000     200         26-38        30.1          15.517     15.577
   100000      50         36-44        39.6          20.046     20.181
  1000000      10         47-52        49.5          24.641     24.785

sorted insertion order
        n    height      mean depth       insert steps    time (ms)
     1000       999           499.5             499500          0.8
    10000      9999          4999.5           49995000         79.1
    20000     19999          9999.5          199990000        409.6

same n = 20000, random order for comparison
    20000        30            17.0             339068          2.2
Three things in this output are worth reading closely:
- Random insertion matches the theory to within 0.7%. For a tree built from n keys in random order, the expected depth of a node is 2(1 + 1/n)Hₙ − 4, where Hₙ is the harmonic number 1 + 1/2 + … + 1/n. Adding one for the node a successful search stops at gives 2(1 + 1/n)Hₙ − 3 compares, the exact version of the “about 2 ln n compares” that Sedgewick and Wayne’s Algorithms gives for a search in a randomly built tree. The
predictedcolumn is that formula, and the measured mean depth sits within 0.7% of it at all four sizes, from 1,000 keys to a million. At a million keys the average node sat at depth 24.6, against 18.0 in a complete tree of the same size, the shallowest shape a million nodes can take. - The height is less predictable than the average depth. Over 1,000 random trees of 1,000 keys, the height ranged from 17 to 29. A balanced tree of the same size has height 9. At a million keys the deepest path averaged 49.5 levels, about 2.6 times the balanced height of 19, but it still grows logarithmically.
- Sorted insertion builds a list. Each new key is larger than everything in the tree, so it goes right at every node: the tree is a chain of height n − 1, and inserting the n keys takes n(n − 1)/2 steps, 199,990,000 for 20,000 keys. Building it took 313 to 410 ms across the six runs, against 2.2 to 2.4 ms for the same keys shuffled. Reversed input builds the mirror-image chain; nearly sorted input comes close to it.
This is the same weakness as quicksort with a first-element pivot, and for the same reason. Building the tree compares each key with every ancestor it passes, which is the same set of comparisons quicksort makes when it takes the first key as pivot and keeps both partitions in their original order, so sorted input is the worst case for both. The quicksort article measures it from the sorting side. The fix in both cases is to stop depending on the input order. For trees, that means a self-balancing tree, such as the red-black tree behind std::set, which rotates nodes on insertion and removal to keep the height logarithmic.
Recursion Depth: When a Traversal Crashes
A recursive traversal on a degenerate tree needs one stack frame per node. The recursive height is the shortest example:
/* Height in edges: -1 for an empty tree, 0 for a single node.
 * Recursive: calls nest height + 2 deep, counting the empty children. */
int bst_height(const Node *t)
{
    if (t == NULL)
        return -1;
    int hl = bst_height(t->left);
    int hr = bst_height(t->right);
    return 1 + (hl > hr ? hl : hr);
}
The test program builds the chain that sorted insertion produces (linked directly, because inserting a million sorted keys would take about 5 × 10¹¹ steps; the test suite checks that the two trees are identical) and asks for its height both ways:
Output (GCC, -O2; the shell’s own “Segmentation fault” message is not part of the program’s output):
$ ./deep_tree 10000000 iterative
n = 10000000, iterative height = 9999999
$ ./deep_tree 1000000 recursive; echo "exit status $?"
n = 1000000, exit status 139
The recursive version printed the start of its line and then died with status 139, which is 128 plus signal 11, SIGSEGV: it ran off the end of the default 8 MiB stack. The depth at which it failed depended on the compiler. Searching for the boundary, the Clang build survived 260,937 levels and crashed at 261,718; the GCC build survived 626,953 and crashed at 627,929. The disassembly of GCC’s -O2 build (objdump -d) explains most of the gap: its bst_height follows the left-child pointer several levels down before it calls itself, so GCC had inlined the recursion into itself and each stack frame covered several tree levels. Built with AddressSanitizer (gcc -O2 -g -fsanitize=address), the crash is reported by name:
AddressSanitizer:DEADLYSIGNAL
=================================================================
==5184==ERROR: AddressSanitizer: stack-overflow on address 0x7ffd8ebe5ff8 (pc 0x55e20ce6b34f bp 0x0000ffffffff sp 0x7ffd8ebe6000 T0)
    #0 0x55e20ce6b34f in bst_height bst.c:181
    #1 0x55e20ce6c5bd in bst_height bst.c:185
    #2 0x55e20ce6c5bd in bst_height bst.c:185
The other languages fail differently, and the difference matters for whether a program can recover. The same recursive height, run on chains of increasing length:
| Language | Default limit on this machine | Recursive height on a chain | What happens |
|---|---|---|---|
C (Clang 18, -O2) | 8 MiB stack | Crashed between 260,937 and 261,718 nodes | Segmentation fault; the process dies |
C (GCC 13, -O2) | 8 MiB stack | Crashed between 626,953 and 627,929 nodes | Segmentation fault; the process dies |
| Java (OpenJDK 21) | 1 MiB thread stack (ThreadStackSize 1024) | Worked at 10,000, failed at 100,000 | StackOverflowError, which can be caught |
| Python 3.13 | Recursion limit 1,000 frames | Worked at 990, failed at 1,000 | RecursionError, which can be caught |
| C# (.NET 10, Linux) | Main thread, 8 MiB stack | Worked at 100,000, failed at 1,000,000 | “Stack overflow.” and the process ends with status 134 |
Microsoft’s documentation states that a StackOverflowException cannot be caught and the process is terminated, so in C#, as in C, the failure takes the whole program down. Python’s limit is low enough that an unbalanced tree of a thousand keys already trips it. None of these limits is a property of the tree; each is a property of the thread running the code. On GitHub’s Ubuntu runner, which allows a larger stack, the AddressSanitizer build that crashed here at a million levels ran to completion. Other threads can have less than the 8 MiB used here: Java’s default thread stack on this machine was 1 MiB, and a C program’s main thread on Windows gets 1 MB by default with Microsoft’s linker.
The iterative versions above avoid the question. Freeing the tree is the one operation that usually stays recursive, and it does not need to: rotating each left child up until a node has none turns the tree into a chain that can be freed in a loop, with no stack and no extra memory:
/* Frees every node without recursion and without extra memory: rotate each
 * left child up until the current node has none, then free it and move right. */
void bst_free(Node *t)
{
    while (t != NULL) {
        if (t->left != NULL) {
            Node *l = t->left;
            t->left = l->right;
            l->right = t;
            t = l;
        } else {
            Node *r = t->right;
            free(t);
            t = r;
        }
    }
}
The test suite frees a million-node chain this way under LeakSanitizer with no leaks reported. The same idea appears in the C++ version’s destructor below, for the reason the stack article demonstrates: a std::unique_ptr chain destroyed recursively overflows the stack in the same way.
Binary Search Tree in C++
The C++ version is a class template over the key type and a comparator, with nodes owned by std::unique_ptr. Insertion uses the same pointer-to-pointer walk as the C code, with std::unique_ptr<Node>* in place of Node **, and the comparator decides equality the way std::set does: two keys are equivalent when neither compares before the other.
    // Returns false if an equivalent key was already present.
    bool insert(T key)
    {
        std::unique_ptr<Node>* link = &root_;
        while (*link) {
            if (comp_(key, (*link)->key))
                link = &(*link)->left;
            else if (comp_((*link)->key, key))
                link = &(*link)->right;
            else
                return false;          // neither is before the other: equivalent
        }
        *link = std::make_unique<Node>(std::move(key));
        ++size_;
        return true;
    }

    [[nodiscard]] bool contains(const T& key) const
    {
        const Node* n = root_.get();
        while (n) {
            if (comp_(key, n->key))
                n = n->left.get();
            else if (comp_(n->key, key))
                n = n->right.get();
            else
                return true;
        }
        return false;
    }

    // Returns false if the key was not present.
    bool erase(const T& key)
    {
        std::unique_ptr<Node>* link = &root_;
        while (*link && (comp_(key, (*link)->key) || comp_((*link)->key, key)))
            link = comp_(key, (*link)->key) ? &(*link)->left : &(*link)->right;
        if (!*link)
            return false;

        Node& n = **link;
        if (!n.left || !n.right) {
            // Take the child out first: assigning *link from a member of the
            // node it owns would destroy that node mid-assignment.
            std::unique_ptr<Node> child = std::move(n.left ? n.left : n.right);
            *link = std::move(child);
        } else {
            // Two children: move the successor's key in, then unlink the
            // successor, which has no left child.
            std::unique_ptr<Node>* succ = &n.right;
            while ((*succ)->left)
                succ = &(*succ)->left;
            n.key = std::move((*succ)->key);
            std::unique_ptr<Node> right = std::move((*succ)->right);
            *succ = std::move(right);
        }
        --size_;
        return true;
    }
Removal moves the surviving child into a local std::unique_ptr before assigning it to *link. Writing *link = std::move(n.right) directly would make the assignment destroy n while it is still reading from n.right, a member of the object being destroyed; it happens to work with the default deleter, but it touches an object after its lifetime ends. The class also has the four traversals, written with a std::vector as a stack and a std::queue, and a destructor built on the same rotation as bst_free:
    // Rotates left children up until the root has none, then drops the
    // root, so destroying even a chain of a million nodes does not recurse.
    void clear() noexcept
    {
        while (root_) {
            if (root_->left) {
                std::unique_ptr<Node> l = std::move(root_->left);
                root_->left = std::move(l->right);
                l->right = std::move(root_);
                root_ = std::move(l);
            } else {
                std::unique_ptr<Node> right = std::move(root_->right);
                root_ = std::move(right);      // frees the old root, which has no children
            }
        }
        size_ = 0;
    }
The demo program prints exactly the output of the C version. Against std::set, which libstdc++ implements as a red-black tree, the comparison program inserts 20,000 keys and then looks each one up:
Output (g++, one of three runs):
n = 20000: insert every key, then look every key up (median of 5, ms)
order      BST height   BinarySearchTree     std::set
random             33                5.1          4.7
sorted          19999              874.1          2.1
On random keys (a different shuffle from the C program’s, which is why the height is 33 rather than 30) the two were close: 4.8 to 5.5 ms for the unbalanced tree and 3.6 to 7.7 ms for std::set across six runs. On sorted keys the unbalanced tree took 801 to 882 ms and std::set 1.4 to 2.1 ms, because the red-black tree stayed balanced while the plain tree became a 19,999-level chain. In C++ code that needs an ordered set or map, std::set and std::map give the logarithmic bound for every insertion order; a hand-written tree is worth writing to learn the structure, or when it needs operations the library does not expose.
Binary Search Tree in Java, Python and C#
The three versions follow the C code: unique keys, iterative insert and search, the two-children removal by successor, and traversals with an explicit stack or a queue. Each prints the same demo output as the C program. The listings show the node, insertion and in-order traversal; removal and the other traversals are in each repository.
Java
The Java class takes a Comparator, and BinarySearchTree.natural() creates one ordered by Comparable. A null key is rejected, since it cannot be compared:
import java.util.ArrayDeque;
import java.util.Comparator;
import java.util.Deque;
import java.util.Objects;
import java.util.function.Consumer;

public final class BinarySearchTree<T> {
    private static final class Node<T> {
        T key;
        Node<T> left;    // keys that compare before key
        Node<T> right;   // keys that compare after key

        Node(T key) {
            this.key = key;
        }
    }

    private final Comparator<? super T> cmp;
    private Node<T> root;
    private int size;

    public BinarySearchTree(Comparator<? super T> cmp) {
        this.cmp = Objects.requireNonNull(cmp);
    }

    /** A tree ordered by the keys' natural ordering. */
    public static <T extends Comparable<? super T>> BinarySearchTree<T> natural() {
        return new BinarySearchTree<>(Comparator.naturalOrder());
    }

    /** Returns false if an equal key was already present. */
    public boolean insert(T key) {
        Objects.requireNonNull(key);
        if (root == null) {
            root = new Node<>(key);
            size++;
            return true;
        }
        Node<T> n = root;
        while (true) {
            int c = cmp.compare(key, n.key);
            if (c == 0) {
                return false;
            }
            Node<T> next = c < 0 ? n.left : n.right;
            if (next == null) {
                if (c < 0) {
                    n.left = new Node<>(key);
                } else {
                    n.right = new Node<>(key);
                }
                size++;
                return true;
            }
            n = next;
        }
    }
    public void inorder(Consumer<? super T> visit) {
        Deque<Node<T>> stack = new ArrayDeque<>();
        Node<T> n = root;
        while (n != null || !stack.isEmpty()) {
            if (n != null) {
                stack.push(n);
                n = n.left;
            } else {
                n = stack.pop();
                visit.accept(n.key);
                n = n.right;
            }
        }
    }
}
The standard library’s ordered collection, java.util.TreeMap, is documented as “a Red-Black tree based NavigableMap implementation” with guaranteed log(n) time for get, put and remove.
Python
Python has no binary search tree in its standard library; the usual tools for ordered data are a sorted list with the bisect module, or heapq for a priority queue. A tree class is still the clearest way to see the structure. Keys only need <, and two keys are equal when neither is smaller:
from __future__ import annotations

from collections.abc import Iterator
from typing import Any, Generic, Protocol, TypeVar


class _Ordered(Protocol):
    def __lt__(self, other: Any, /) -> bool: ...


K = TypeVar("K", bound=_Ordered)


class _Node(Generic[K]):
    __slots__ = ("key", "left", "right")

    def __init__(self, key: K) -> None:
        self.key = key
        self.left: _Node[K] | None = None    # keys smaller than key
        self.right: _Node[K] | None = None   # keys larger than key


class BinarySearchTree(Generic[K]):
    """Keys are compared with <; two keys are equal when neither is smaller."""

    def __init__(self) -> None:
        self._root: _Node[K] | None = None
        self._size = 0

    def insert(self, key: K) -> bool:
        """Return False if the key was already present."""
        if self._root is None:
            self._root = _Node(key)
            self._size += 1
            return True
        n = self._root
        while True:
            if key < n.key:
                if n.left is None:
                    n.left = _Node(key)
                    break
                n = n.left
            elif n.key < key:
                if n.right is None:
                    n.right = _Node(key)
                    break
                n = n.right
            else:
                return False
        self._size += 1
        return True
    def inorder(self) -> Iterator[K]:
        stack: list[_Node[K]] = []
        n = self._root
        while n is not None or stack:
            if n is not None:
                stack.append(n)
                n = n.left
            else:
                n = stack.pop()
                yield n.key
                n = n.right
Writing these methods recursively would be shorter, and on a tree built from a thousand sorted keys it would raise RecursionError, as the table above shows. The traversals are generators, so for key in tree and list(tree) work without building a list first.
C#
The C# class takes an IComparer<T> and exposes the traversals as IEnumerable<T>, written with yield return over a Stack<T> or Queue<T>:
using System;
using System.Collections.Generic;

namespace MyCPlus.BinaryTree;

public sealed class BinarySearchTree<T>
{
    private sealed class Node(T key)
    {
        public T Key { get; set; } = key;
        public Node? Left { get; set; }    // keys that compare before Key
        public Node? Right { get; set; }   // keys that compare after Key
    }

    private readonly IComparer<T> _cmp;
    private Node? _root;

    public BinarySearchTree() : this(Comparer<T>.Default) { }

    public BinarySearchTree(IComparer<T> comparer)
    {
        ArgumentNullException.ThrowIfNull(comparer);
        _cmp = comparer;
    }

    public int Count { get; private set; }

    /// <summary>Returns false if an equal key was already present.</summary>
    public bool Insert(T key)
    {
        ArgumentNullException.ThrowIfNull(key);
        if (_root is null)
        {
            _root = new Node(key);
            Count++;
            return true;
        }
        Node n = _root;
        while (true)
        {
            int c = _cmp.Compare(key, n.Key);
            if (c == 0)
                return false;
            Node? next = c < 0 ? n.Left : n.Right;
            if (next is null)
            {
                if (c < 0)
                    n.Left = new Node(key);
                else
                    n.Right = new Node(key);
                Count++;
                return true;
            }
            n = next;
        }
    }
    public IEnumerable<T> Inorder()
    {
        var stack = new Stack<Node>();
        Node? n = _root;
        while (n is not null || stack.Count > 0)
        {
            if (n is not null)
            {
                stack.Push(n);
                n = n.Left;
            }
            else
            {
                n = stack.Pop();
                yield return n.Key;
                n = n.Right;
            }
        }
    }
}
.NET’s SortedSet<T> is a red-black tree, as the comments in its source state.
Five Binary Tree Mistakes That Compile
Each of these compiled with -Wall -Wextra -pedantic, and most of them print plausible output. The four C mistakes are in the C repository’s pitfalls/ directory and the C++ one in the C++ repository’s, and the builds run each one and check the line of its output that shows the bug.
1. Inserting Through a Copy of the Root Pointer
A recursive insert that passes the root pointer by value compiles cleanly:
void insert_by_value(Node *root, int key)
{
    if (root == NULL) {
        root = malloc(sizeof *root);    /* assigns the parameter, not the caller's pointer */
        if (root == NULL)
            return;
        root->key = key;
        root->left = root->right = NULL;
    } else if (key < root->key) {
        insert_by_value(root->left, key);
    } else if (key > root->key) {
        insert_by_value(root->right, key);
    }
}
Output:
after 5 inserts: size 0, root NULLroot = malloc(...) assigns the function’s own copy of the pointer, which disappears when the function returns, so the caller’s tree stays empty however many keys go in. Neither GCC nor Clang warned. LeakSanitizer finds the five nodes that were allocated and lost:
=================================================================
==3249==ERROR: LeakSanitizer: detected memory leaks
Direct leak of 120 byte(s) in 5 object(s) allocated from:
    #0 0x7fe10fefd9c7 in malloc ../../../../src/libsanitizer/asan/asan_malloc_linux.cpp:69
    #1 0x55c2c004328b in insert_by_value insert_by_value.c:14
The fix is to pass the address of the pointer to be changed, as bst_insert does with Node **, or to return the new subtree root and have the caller assign it.
2. Checking the Ordering Rule Only Between Parent and Child
A binary search tree check that compares each node with its two children looks complete and is not:
bool is_bst_local(const Node *t)
{
    if (t == NULL)
        return true;
    if (t->left != NULL && t->left->key >= t->key)
        return false;
    if (t->right != NULL && t->right->key <= t->key)
        return false;
    return is_bst_local(t->left) && is_bst_local(t->right);
}

/* Correct: every key must lie strictly between the bounds its ancestors set.
 * long long bounds let INT_MIN and INT_MAX be keys. */
bool is_bst_range(const Node *t, long long lo, long long hi)
{
    if (t == NULL)
        return true;
    if (t->key <= lo || t->key >= hi)
        return false;
    return is_bst_range(t->left, lo, t->key) && is_bst_range(t->right, t->key, hi);
}
Output:
local check:  BST
range check:  not a BST
contains 60:  no
The tree tested has 60 as the right child of 30, under 50. Every parent-child pair is in order, so the local check passes, but 60 is in the left subtree of 50 and is larger than 50. A search for 60 goes right at the root and never finds it. The correct check passes down the range of keys each subtree may hold. The bounds are long long so that INT_MIN and INT_MAX can be stored as keys; with int bounds, one of those two values would always be rejected.
3. Removing the Wrong Key After Copying the Successor
The usual recursive removal copies the successor’s key into the node and then removes the successor from the right subtree. Passing the key being removed at that point is an easy slip:
Node *remove_rec(Node *t, int key)
{
    if (t == NULL)
        return NULL;
    if (key < t->key) {
        t->left = remove_rec(t->left, key);
    } else if (key > t->key) {
        t->right = remove_rec(t->right, key);
    } else if (t->left == NULL || t->right == NULL) {
        Node *child = t->left != NULL ? t->left : t->right;
        free(t);
        return child;
    } else {
        const Node *succ = t->right;
        while (succ->left != NULL)
            succ = succ->left;
        t->key = succ->key;
        t->right = remove_rec(t->right, key);   /* bug: should be succ's key, now t->key */
    }
    return t;
}
Output:
after removing 30: 20 35 35 40 45 50 60 65 70 80
size 10, contains 30: no
after removing 35: 20 35 40 45 50 60 65 70 80
size 9, contains 35: yes
The key being removed is not in the right subtree, so the second call finds nothing and returns. The tree now holds 35 twice and its size has not changed. Removing 35 later removes one copy and leaves the other, so contains 35 still answers yes. In-order output that is sorted but has a repeated key is the symptom; a test that only checks sortedness does not see it. The fix is to pass t->key, which now holds the successor’s key.
4. Freeing a Node Before Its Children
A recursive free in preorder releases the node and then reads its child pointers from the freed block:
void free_preorder(Node *t)
{
    if (t == NULL)
        return;
    free(t);
    free_preorder(t->left);     /* reads freed memory */
    free_preorder(t->right);
}
GCC 13 flagged it at compile time; Clang 18 printed nothing:
free_preorder.c: In function 'free_preorder':
free_preorder.c:18:20: warning: pointer 't' used after 'free' [-Wuse-after-free]
   18 |     free_preorder(t->right);
      |                   ~^~~~~~~
free_preorder.c:16:5: note: call to 'free' here
   16 |     free(t);
      |     ^~~~~~~
free_preorder.c:17:20: warning: pointer 't' used after 'free' [-Wuse-after-free]
   17 |     free_preorder(t->left);     /* reads freed memory */
      |                   ~^~~~~~
free_preorder.c:16:5: note: call to 'free' here
   16 |     free(t);
      |     ^~~~~~~
Run without a sanitizer, the program crashed with a segmentation fault at -O0 and at -O2, under both compilers. That is a property of this allocator rather than of the bug: glibc 2.39 writes a check value into the second 8 bytes of a freed small block, which is exactly where left sits in this 24-byte node, so the next call follows a garbage pointer. With another allocator or another node layout the same code may appear to work. AddressSanitizer reports the read either way:
=================================================================
==3269==ERROR: AddressSanitizer: heap-use-after-free on address 0x503000000048 at pc 0x55b06bd0428c bp 0x7ffd605cf270 sp 0x7ffd605cf260
READ of size 8 at 0x503000000048 thread T0
    #0 0x55b06bd0428b in free_preorder free_preorder.c:17
The fix is postorder: free both children first, then the node. bst_free above avoids the recursion as well.
5. A Comparator That Is Not a Strict Ordering (C++)
The C++ tree decides that two keys are equal when neither compares before the other, which is the rule std::set uses. With std::less_equal as the comparator, a key compares before itself, so the tree never sees a duplicate:
    BinarySearchTree<int, std::less_equal<int>> tree;
    for (int key : {50, 30, 70, 40, 40})
        tree.insert(key);
    std::cout << "size after inserting 50 30 70 40 40: " << tree.size() << '\n';
    std::cout << "contains 40: " << (tree.contains(40) ? "yes" : "no") << '\n';
    std::cout << "erase 40: " << (tree.erase(40) ? "removed" : "not found") << '\n';
Output:
size after inserting 50 30 70 40 40: 5
contains 40: no
erase 40: not found
in order: 30 40 40 50 70
The second 40 went into the left subtree of the first, and a search for 40 then went left past both copies. The tree holds the key twice and reports that it holds it zero times. The comparator must be a strict weak ordering, < and not <=, and the same requirement applies to std::set, std::map and std::sort.
Key Takeaways
- A binary search tree costs one step per level, so its shape decides its speed. Random insertion of a million keys gave heights of 47 to 52; sorted insertion of 20,000 gave a chain of 19,999 that took 130 to 190 times as long to build.
- Random trees behave as the theory predicts. The measured mean node depth stayed within 0.7% of 2(1 + 1/n)Hₙ − 4 from 1,000 to 1,000,000 keys.
- Recursion depth is a property of the thread, not the tree. A recursive height crashed at about 261,000 levels with Clang and 627,000 with GCC on an 8 MiB stack, and Python’s default limit stops it at about 1,000.
- Iterative walks and a rotating free remove the limit. An explicit stack, a queue, and rotating left children up before freeing handled a million-node chain in the tests, and the iterative height a ten-million-node one.
- Removal with two children uses the in-order successor. The successor has no left child, so removing it is one of the easy cases.
- The ordering rule is global. A check that compares only parents and children accepts a tree in which a search cannot find a key.
- For production code, use a balanced tree.
std::setstayed at 1.4 to 2.1 ms on sorted input where the plain tree took 801 to 882 ms.
Conclusion
A binary search tree is usually introduced as a logarithmic structure, and the measurements here show what that claim depends on. With keys in random order it held up well, and it matched the expected-depth formula closely. With keys in sorted order, which is how a great deal of real data arrives, the same code built a list, and the recursive traversals that make tree code so short turned that list into a crash whose depth depended on the compiler and the language.
That is the case for writing the iterative versions once and understanding why they work, and then for reaching for a balanced tree in production. Red-black trees and AVL trees keep the same ordering rule and the same traversals, and add rotations that keep the height logarithmic for any input. The data structures section continues from here.
Source Code and Tests
The code is in five repositories, one per language, each in a data-structures/binary-tree directory with its own workflow:
| Language | Repository | Build |
|---|---|---|
| C | mycplus/c-examples |  |
| C++ | mycplus/cpp-examples |  |
| Java | mycplus/java-examples |  |
| Python | mycplus/python-examples |  |
| C# | mycplus/csharp-examples |  |
Build and test the C or C++ version with:
cmake -S . -B build
cmake --build build
ctest --test-dir build --output-on-failure
What the builds check on each change:
- Compilation with warnings as errors: GCC and Clang with
-Wall -Wextra -pedantic -Werror(C11 and C17; C++17 and C++20) and MSVC with/W4 /WX; Java with-Xlint:all -Werroron Java 17, 21 and 25; Python withruffandmypy --stricton 3.10 to 3.14; C# with analyzer warnings as errors on Linux, Windows and macOS. - Correctness against a reference: in every language, 200,000 random inserts, removals and searches are checked against the standard library’s set (a presence table in C), including the smallest and largest
intvalues in C, C++, Java and C#, plus every removal case and an empty tree. - Depth without recursion: a 1,000,000-node chain is walked and freed in C; in Java and C#, a 20,000-node chain is walked on a thread with a 64 KiB and a 256 KiB stack, where a recursive walk overflows; Python walks a 3,000-node chain, three times its recursion limit; and the C++ destructor frees a 20,000-node chain on a thread with a 64 KiB stack.
- The printed output on this page: each language’s demo is compared with the output block above, byte for byte apart from Windows line endings.
- Sanitizers and pitfalls: the C and C++ tests run under AddressSanitizer and UndefinedBehaviorSanitizer. Each of the five pitfall programs is run and checked for the output line that shows its bug (the empty tree and the leak, the accepted non-BST, the duplicated key, GCC’s warning and ASan’s report, the unfindable key), and the recursive heights are checked to overflow the stack in C, Java and C# and to raise
RecursionErrorin Python.
The builds do not run the timing programs, because timings depend on the machine. A green badge means the code builds on those toolchains and passes those tests; it does not reproduce the timings above.