
Insertion sort’s running cost can be predicted before it runs. It moves an element once for every pair of values that are out of order in the input, called an inversion, and that count settles everything else. Measured on five arrangements of 10,000 values, the number of element moves equaled the inversion count exactly every time. It ranged from 0 on sorted input to 49,994,942 on reversed input, and the number of comparisons was never more than n − 1 above it.
This guide traces insertion sort on a small array, then gives implementations in C, C++, Java, Python and C#. It measures the inversion count against real inputs and covers binary insertion sort. It also looks at why standard libraries hand small arrays to insertion sort, and at three mistakes that compile. Every program was compiled and run for this article on Ubuntu 24.04: C with GCC 13.3 and Clang 18.1.3 (-std=c11 and -std=c17), C++ with g++ 13.3 and clang++ 18.1.3 (-std=c++17 and -std=c++20), all with -Wall -Wextra -pedantic and no warnings except where a pitfall is shown; Java on OpenJDK 21, Python 3.11, and C# on Mono 6.8. All five sort the same array and print the same result. The C and C++ code is in GitHub repositories whose builds run the tests on each change.
What Is Insertion Sort?
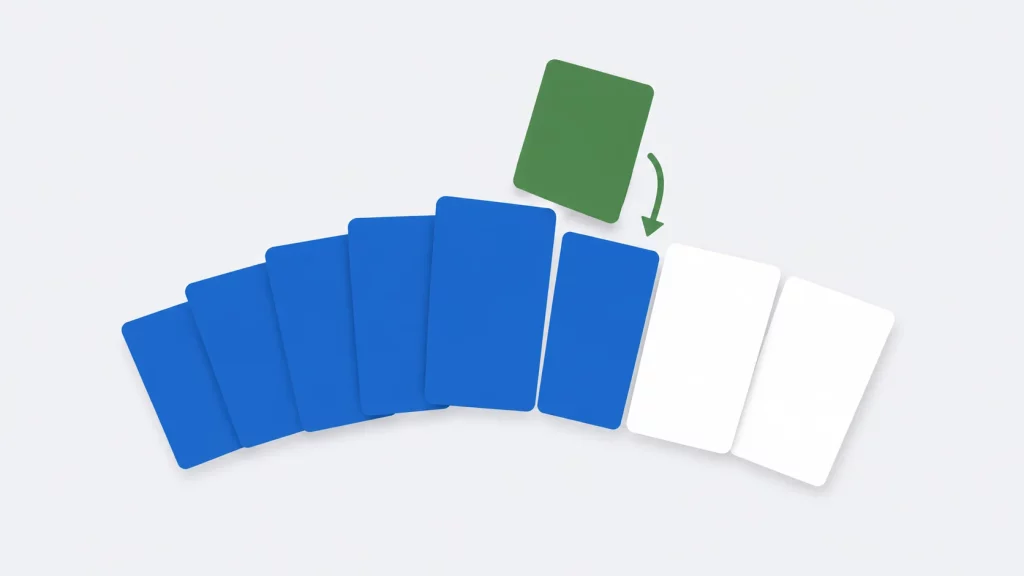
Insertion sort is a comparison sorting algorithm that builds a sorted prefix one element at a time. It takes the next element, shifts every larger element in the prefix one position right, and drops the element into the gap. It is stable, sorts in place with O(1) extra memory, runs in O(n) time on sorted input and O(n²) in the worst case.
It is the way many people sort a hand of playing cards: pick up one card, slide it left past the cards that are larger, and put it down. It also runs inside production sorts: libstdc++’s std::sort finishes with insertion sort once its partitions are small, and CPython’s list.sort() builds its short runs with a binary insertion sort.
How Insertion Sort Works
- Treat the first element as a sorted prefix of length one.
- Take the next element
v = a[i]out of the array. - Shift left to right: while the element before the gap is larger than
v, move it one place right. - Drop
vinto the gap. The prefixa[0..i]is now sorted. - Repeat for every
iup ton − 1.
The comparison in step 3 is strict: an element moves only past values that are strictly larger. That is what makes the sort stable, because an equal value already in the prefix is never jumped.
Worked Example
Sorting 29 10 14 37 13 5 41 22, as printed by the trace program in the repository:
Output:
start:                  29  10  14  37  13   5  41  22
insert 10 (1 moved):    10  29  14  37  13   5  41  22
insert 14 (1 moved):    10  14  29  37  13   5  41  22
insert 37 (0 moved):    10  14  29  37  13   5  41  22
insert 13 (3 moved):    10  13  14  29  37   5  41  22
insert 5 (5 moved):      5  10  13  14  29  37  41  22
insert 41 (0 moved):     5  10  13  14  29  37  41  22
insert 22 (3 moved):     5  10  13  14  22  29  37  41
binary insertion:        5  10  13  14  22  29  37  41
limits: -2147483648 -1 0 0 2147483647
empty array: okTwo rows cost nothing: 37 and 41 are larger than everything before them, so each is compared once and stays where it is. Inserting 5 costs the most, five moves, because it is smaller than all five values in the prefix. The moves add up to 1 + 1 + 0 + 3 + 5 + 0 + 3 = 13, and the input has exactly 13 inversions. The next section shows that this equality is not a coincidence of the example.
Insertion Sort in C
The header declares two functions, the standard version and the binary insertion variant covered later:
/* insertion_sort.h - insertion sort and binary insertion sort for int arrays */
#ifndef INSERTION_SORT_H
#define INSERTION_SORT_H

#include <stddef.h>

void insertion_sort(int a[], size_t n);
void binary_insertion_sort(int a[], size_t n);

#endif
Both functions route every comparison through SORT_LESS(x, y), meaning “x sorts before y”. It is plain < unless a test program redefines it to count comparisons:
/* insertion_sort.c - insertion sort in C11.
 * SORT_LESS(x, y) means "x sorts before y". Test programs redefine it
 * before including this file, to count comparisons. */
#include <string.h>
#include "insertion_sort.h"

#ifndef SORT_LESS
#define SORT_LESS(x, y) ((x) < (y))
#endif

/* Stable, in place. O(n) on sorted input, O(n^2) worst case. */
void insertion_sort(int a[], size_t n)
{
    for (size_t i = 1; i < n; i++) {
        int v = a[i];                        /* the element being inserted */
        size_t j = i;
        while (j > 0 && SORT_LESS(v, a[j - 1])) {
            a[j] = a[j - 1];                 /* shift the larger one right */
            j--;
        }
        a[j] = v;
    }
}

/* Binary insertion sort: finds each insertion point by binary search,
 * then shifts with memmove. Fewer comparisons, the same element moves.
 * Searching for the first element greater than v keeps it stable. */
void binary_insertion_sort(int a[], size_t n)
{
    for (size_t i = 1; i < n; i++) {
        int v = a[i];
        size_t lo = 0, hi = i;               /* insertion point is in [lo, hi] */
        while (lo < hi) {
            size_t mid = lo + (hi - lo) / 2;
            if (SORT_LESS(v, a[mid]))
                hi = mid;
            else
                lo = mid + 1;
        }
        memmove(&a[lo + 1], &a[lo], (i - lo) * sizeof a[0]);
        a[lo] = v;
    }
}
A short program that calls both:
/* insertion_example.c - calls both functions from insertion_sort.c */
#include <stdio.h>
#include <limits.h>
#include "insertion_sort.h"

static void print_array(const char *label, const int a[], size_t n)
{
    printf("%-10s", label);
    for (size_t i = 0; i < n; i++)
        printf(" %d", a[i]);
    printf("\n");
}

int main(void)
{
    int a[] = { 29, 10, 14, 37, 13, 5, 41, 22 };
    int b[] = { 29, 10, 14, 37, 13, 5, 41, 22 };
    int edge[] = { 0, INT_MAX, -1, INT_MIN, 0 };
    size_t n = sizeof a / sizeof a[0];

    print_array("before:", a, n);
    insertion_sort(a, n);
    print_array("after:", a, n);
    binary_insertion_sort(b, n);
    print_array("binary:", b, n);
    insertion_sort(edge, 5);
    print_array("limits:", edge, 5);
    insertion_sort(NULL, 0);             /* empty: the loop never runs */
    return 0;
}
Output:
before:    29 10 14 37 13 5 41 22
after:     5 10 13 14 22 29 37 41
binary:    5 10 13 14 22 29 37 41
limits:    -2147483648 -1 0 0 2147483647
Four details of the C version carry the correctness:
- The index
jcounts down to 0 and stops there. The loop condition isj > 0and the comparison readsa[j - 1], so no index goes below zero. Withsize_t n = 0the outer loop’si < nis false at once, which is whyinsertion_sort(NULL, 0)is safe. - The element is held in
v, not swapped. Each step is one assignment,a[j] = a[j - 1], rather than a three-assignment swap. - The comparison is strict.
SORT_LESS(v, a[j - 1])is false for equal values, so equal elements keep their input order. - Values are compared, never subtracted, so
INT_MINandINT_MAXsort correctly, as thelimits:line shows.
Why Insertion Sort’s Cost Is the Inversion Count
An inversion is a pair of positions i < j with a[i] > a[j]. Each shift in insertion sort moves one larger element past v, which fixes exactly one inversion and creates none. So the number of shifts equals the number of inversions in the input. Each comparison either causes a shift or ends the inner loop, and the loop ends by comparison at most once per element. That puts the comparison count between the inversion count and the inversion count plus n − 1.
The counting program checks both statements on 10,000 values in five arrangements. The inversion count comes from a separate O(n²) loop that does not share code with the sort:
Output:
n = 10000        inversions  comparisons        moves   binary cmp    moves-inv
sorted                            0         9999            0       113631            0
reversed                   49994942     49995000     49994942       123617            0
random                     25183572     25193556     25183572       119071            0
local (within 8)              17736        27735        17736       116503            0
100 far swaps                810213       820212       810213       118834            0
The moves-inv column is 0 on every row: moves and inversions agreed exactly. The comparison count exceeded the inversion count by at most 9,999 (the sorted row; on the reversed row the gap was only 58, because most elements travel all the way to the front and end their loop on j > 0 without a final comparison).
The two “nearly sorted” rows show what the equality means in practice:
- “Local (within 8)”: each element was shuffled inside its block of 8, so none is more than 7 positions from home. That cost 27,735 comparisons. Binary insertion sort made 116,503 on the same input, and any comparison sort needs about log₂(10,000!) ≈ 118,458 comparisons in its worst case at this size.
- “100 far swaps”: only 200 values are out of place, but each swap exchanged two random positions, often thousands apart. That created 810,213 inversions, and insertion sort paid for every one, while binary insertion sort made 118,834 comparisons on the same input.
So “insertion sort is fast on nearly sorted data” is true only for the right kind of nearly sorted. It pays for how far elements are from home, summed over all elements, not for how many are out of place. If every element is within k positions of its final place, insertion sort runs in O(nk) time.
Binary Insertion Sort
The shifting loop finds the insertion point by walking left one comparison at a time. A binary search over the sorted prefix finds the same point in about log₂ i comparisons, and memmove then shifts the block in one call. The binary cmp column above shows the effect: 113,631 to 123,617 comparisons on every input, against up to 49,995,000 for the plain version.
It does not change the number of element moves, which is still the inversion count, so binary insertion sort is still O(n²). It helps when comparisons are expensive, such as strings or records compared through a function, and when a block move is faster than a loop of single moves. The search looks for the first element greater than v, so equal elements stay in input order and the variant remains stable.
How This Was Measured
| Setting | Value |
|---|---|
| Date tested | September 2026 |
| Hardware | Intel Xeon at 2.10 GHz, cloud VM, nproc reports 2; all code single-threaded |
| Operating system | Ubuntu 24.04, glibc 2.39 |
| Compilers | GCC 13.3 and Clang 18.1.3, -O2 |
| Input | Pseudo-random int values in [0, 999,999,999] from a fixed-seed xorshift generator |
| What is timed | The sort calls only, with clock_gettime(CLOCK_MONOTONIC) |
| Statistic | Median of 5 runs; the program was run three times per compiler and ranges are the spread of those medians |
| Correctness check | Every sorted array is checked for order before its time is kept |
No CPU pinning or frequency-scaling control was used, and all figures come from this one virtual machine. The comparison and move counts above do not depend on the machine; the timings below do.
Where Insertion Sort Beats qsort()
One run of the timing program built with GCC:
Output:
one array of 20000 random ints, ms (median of 5)
  insertion sort             36.68
  binary insertion sort       5.36
  qsort()                     2.24

2000000 ints sorted as arrays of n, ns per element
       n    insertion  binary ins.      qsort()
       4          5.9         10.7         17.7
       8          9.4         16.0         22.3
      16         12.6         22.1         30.7
      32         16.1         30.1         38.1
      64         21.3         38.6         44.6
     128         32.3         49.7         53.2
     256         44.4         56.3         61.9
     512         66.4         68.5         73.6
On one array of 20,000 elements, insertion sort took 34.5–36.7 ms with GCC and 58.6–60.6 ms with Clang across three runs, against 2.1–2.2 ms for qsort(). Binary insertion sort took 5.2–5.4 ms under both compilers, about 6.5 times faster than the plain version on GCC, because memmove shifts a block far faster than the element-by-element loop.
The lower table sorts the same 2,000,000 values as many small arrays. Up to n = 256, insertion sort was faster per element than qsort() in every run under both compilers. At n = 16 it took 12.2–12.8 ns per element with GCC against 30.7–32.4 ns for qsort(), about 2.5 times faster. The advantage shrinks as n grows. At 512 the three were close with GCC, all between 65 and 76 ns per element, while Clang’s insertion sort took 88–95 ns against 68–69 ns for qsort(). The quadratic term has caught up.
This is why production sorts switch to insertion sort for small ranges. Three that were checked in their sources for this article:
| Library | Where insertion sort is used |
|---|---|
libstdc++ 13 std::sort (GCC’s C++ library) | Introsort stops partitioning at 16 elements (_S_threshold = 16), then one insertion sort pass finishes the whole array |
OpenJDK 21 Arrays.sort(int[]) | Insertion sort for leftmost parts under 44 elements (MAX_INSERTION_SORT_SIZE); a mixed insertion sort for other small parts, with a limit based on MAX_MIXED_INSERTION_SORT_SIZE = 65 |
CPython list.sort() | Runs shorter than the minimum run length are extended with a stable binary insertion sort; small lists are sorted that way entirely |
The thresholds differ, and each library tunes its own. The measurements here put the crossover against qsort() between 256 and 512 elements for plain int values on this machine. The libraries switch at smaller sizes, but their trade-off is different: inside a hybrid sort, insertion sort competes with the recursive algorithm’s own cost on a small range, not with a separate qsort() call, so these numbers do not say where a library’s threshold should be.
Three Insertion Sort Mistakes That Compile
1. An Unsigned Index With j >= 0
Many textbooks write the inner loop counting j down from i - 1 while j >= 0. With a size_t index that condition is always true, because an unsigned value cannot be negative:
/* unsigned_index.c - the textbook loop "j >= 0" with a size_t index */
#include <stdio.h>
#include <stddef.h>

void insertion_sort_unsigned(int a[], size_t n)
{
    for (size_t i = 1; i < n; i++) {
        int v = a[i];
        size_t j;
        for (j = i - 1; j >= 0 && a[j] > v; j--)   /* j >= 0 is always true */
            a[j + 1] = a[j];
        a[j + 1] = v;
    }
}

int main(void)
{
    int a[] = { 3, 1, 2 };
    insertion_sort_unsigned(a, 3);
    printf("%d %d %d\n", a[0], a[1], a[2]);
    return 0;
}
GCC’s -Wextra flags it:
unsigned_index.c:10:27: warning: comparison of unsigned expression in '>= 0' is always true [-Wtype-limits]Clang 18 with -Wall -Wextra printed no warning. When j passes zero it wraps to SIZE_MAX, and a[j] becomes a read one element before the array. What that read returns depends on the stack, and the results showed it:
| Build | Output over repeated runs |
|---|---|
GCC 13.3 -O2 | 1 2 3 in all three runs, which looks correct |
Clang 18.1.3 -O2 | Five runs, four different results: 2 32767 3, 2 32765 3 (twice), 1887144864 32766 3, 1506170192 32765 3 |
GCC with -fsanitize=address | stack-buffer-underflow, READ of size 4 |
The GCC build passing three runs in a row is how this bug survives testing. Write the loop so the index never needs to go below zero: while (j > 0 && v < a[j - 1]), as in the C version above.
2. Reading and Modifying j in One Expression
A compact form of the shift loop moves an element and decrements the index in one statement:
/* unsequenced.c - reading and modifying j in one expression */
#include <stdio.h>

void insertion_sort_unsequenced(int a[], int n)
{
    for (int i = 1; i < n; i++) {
        int v = a[i];
        int j = i;
        while (j > 0 && a[j - 1] > v)
            a[j--] = a[j - 1];                     /* undefined behavior */
        a[j] = v;
    }
}

int main(void)
{
    int a[] = { 29, 10, 14, 37, 13, 5, 41, 22 };
    insertion_sort_unsequenced(a, 8);
    for (int i = 0; i < 8; i++)
        printf("%d ", a[i]);
    printf("\n");
    return 0;
}
a[j--] = a[j - 1] reads j on the right and modifies it on the left with no sequence point between them, which is undefined behavior in C. Both compilers warned:
unsequenced.c:10:16: warning: operation on 'j' may be undefined [-Wsequence-point]
unsequenced.c:10:16: warning: unsequenced modification and access to 'j' [-Wunsequenced]
Both builds then printed the correctly sorted 5 10 13 14 22 29 37 41. The code producing the right answer on two compilers is not evidence that it is correct; a different optimization level or compiler version is free to evaluate the two sides in the other order. Write the move and the decrement as separate statements.
3. <= Instead of <
This program sorts records by key twice, once with the strict comparison and once with <=. The letters record the original order of equal keys:
/* stability.c - "<=" instead of "<" still sorts, but reorders equal keys */
#include <stdio.h>
#include <stddef.h>

typedef struct { int key; char tag; } Item;

static void sort_items(Item a[], size_t n, int use_lte)
{
    for (size_t i = 1; i < n; i++) {
        Item v = a[i];
        size_t j = i;
        while (j > 0 && (use_lte ? v.key <= a[j - 1].key : v.key < a[j - 1].key)) {
            a[j] = a[j - 1];
            j--;
        }
        a[j] = v;
    }
}

static void show(const char *label, const Item a[], size_t n)
{
    printf("%s", label);
    for (size_t i = 0; i < n; i++)
        printf(" %d%c", a[i].key, a[i].tag);
    printf("\n");
}

int main(void)
{
    Item x[] = { {2,'a'}, {1,'b'}, {2,'c'}, {1,'d'}, {2,'e'} };
    Item y[] = { {2,'a'}, {1,'b'}, {2,'c'}, {1,'d'}, {2,'e'} };
    show("input:         ", x, 5);
    sort_items(x, 5, 0);
    show("v <  a[j - 1]: ", x, 5);
    sort_items(y, 5, 1);
    show("v <= a[j - 1]: ", y, 5);
    return 0;
}
Output:
input:          2a 1b 2c 1d 2e
v <  a[j - 1]:  1b 1d 2a 2c 2e
v <= a[j - 1]:  1d 1b 2e 2c 2a
Both results are sorted by key, so a test that only checks order passes both. With <=, each equal key is shifted past the ones before it, and both groups came out reversed. It also costs extra moves: every equal pair now counts as a shift.
Insertion Sort Time and Space Complexity
| Case | Comparisons | Moves | When |
|---|---|---|---|
| Best | n − 1 | 0 | Already sorted |
| Average | about n²/4 | about n²/4 | Random order: n(n − 1)/4 inversions expected |
| Worst | n(n − 1)/2 | n(n − 1)/2 | Reversed, all values distinct |
| Every element within k of home | O(nk) | O(nk) | Locally shuffled data |
| Extra memory | O(1) | In place |
For the random 10,000-element input, the expected inversion count is n(n − 1)/4 = 24,997,500; the measured count was 25,183,572, within 0.75% of it. Insertion sort is stable and adaptive: its running time follows the disorder in the input rather than just its size.
Insertion Sort in C++, Java, Python and C#
C++
The C++ version is a template over bidirectional iterators with a comparator, like the standard algorithms. It needs to step backward, so it works on std::list but not std::forward_list:
// insertion_sort.hpp - generic insertion sort for C++17
#ifndef INSERTION_SORT_HPP
#define INSERTION_SORT_HPP

#include <algorithm>
#include <functional>
#include <iterator>
#include <utility>

// Stable, in place. Needs only bidirectional iterators, so it also sorts
// a std::list. comp(a, b) means "a goes before b", as in std::sort.
template <class BidirIt, class Compare = std::less<>>
void insertion_sort(BidirIt first, BidirIt last, Compare comp = {})
{
    if (first == last)
        return;
    for (BidirIt i = std::next(first); i != last; ++i) {
        auto v = std::move(*i);
        BidirIt j = i;
        for (BidirIt prev = std::prev(j); comp(v, *prev); --prev) {
            *j = std::move(*prev);           // shift the larger element right
            --j;
            if (prev == first)
                break;
        }
        *j = std::move(v);
    }
}

// Binary insertion sort: std::upper_bound finds the insertion point, which
// keeps it stable; std::rotate shifts the block. Random-access iterators.
template <class RandomIt, class Compare = std::less<>>
void binary_insertion_sort(RandomIt first, RandomIt last, Compare comp = {})
{
    for (RandomIt i = first; i != last; ++i)
        std::rotate(std::upper_bound(first, i, *i, comp), i, std::next(i));
}

#endif
// insertion_demo.cpp - the generic insertion sort on four containers
#include <algorithm>
#include <functional>
#include <iostream>
#include <list>
#include <string>
#include <vector>
#include "insertion_sort.hpp"
template <class Range>
void print(const char* label, const Range& r)
{
std::cout << label;
for (const auto& x : r) std::cout << ' ' << x;
std::cout << '\n';
}
struct Employee {
std::string name;
int dept;
};
int main()
{
std::vector<int> v{29, 10, 14, 37, 13, 5, 41, 22};
insertion_sort(v.begin(), v.end());
print("ascending: ", v);
insertion_sort(v.begin(), v.end(), std::greater<>{});
print("descending:", v);
std::list<std::string> words{"pear", "fig", "apple", "kiwi", "date"};
insertion_sort(words.begin(), words.end());
print("std::list: ", words);
std::vector<int> w{29, 10, 14, 37, 13, 5, 41, 22};
binary_insertion_sort(w.begin(), w.end());
print("binary: ", w);
std::vector<Employee> staff{
{"Ava", 2}, {"Ben", 1}, {"Cleo", 2}, {"Dev", 1}, {"Eli", 3}, {"Fay", 1}};
auto expected = staff;
auto by_dept = [](const Employee& a, const Employee& b) { return a.dept < b.dept; };
insertion_sort(staff.begin(), staff.end(), by_dept);
std::stable_sort(expected.begin(), expected.end(), by_dept);
std::cout << "by dept: ";
for (const auto& e : staff) std::cout << ' ' << e.dept << ':' << e.name;
bool same = std::equal(staff.begin(), staff.end(), expected.begin(),
[](const Employee& a, const Employee& b) { return a.name == b.name; });
std::cout << "\nmatches std::stable_sort: " << (same ? "yes" : "no") << '\n';
return 0;
}Output (g++ 13.3 and clang++ 18.1.3, identical):
ascending:  5 10 13 14 22 29 37 41
descending: 41 37 29 22 14 13 10 5
std::list:  apple date fig kiwi pear
binary:     5 10 13 14 22 29 37 41
by dept:    1:Ben 1:Dev 1:Fay 2:Ava 2:Cleo 3:Eli
matches std::stable_sort: yes
The inner loop checks prev == first after moving, so it never decrements an iterator past the beginning, which is undefined behavior for standard containers. binary_insertion_sort is three standard algorithms: std::upper_bound finds the first element greater than the new one, which keeps the sort stable, and std::rotate shifts the block and places the element in one call.
Java
// InsertionSort.java - insertion sort in Java 21
import java.util.Arrays;

public class InsertionSort {

    // Stable, in place: the strict < never moves an element past an equal one.
    static void insertionSort(int[] a) {
        for (int i = 1; i < a.length; i++) {
            int v = a[i];
            int j = i;
            while (j > 0 && v < a[j - 1]) {
                a[j] = a[j - 1];
                j--;
            }
            a[j] = v;
        }
    }

    public static void main(String[] args) {
        int[] data = {29, 10, 14, 37, 13, 5, 41, 22};
        insertionSort(data);
        System.out.println("Sorted: " + Arrays.toString(data));
    }
}
Sorted: [5, 10, 13, 14, 22, 29, 37, 41]Python
"""Insertion sort in Python 3."""


def insertion_sort(a: list[int]) -> list[int]:
    """Sort list a in place. Stable: equal elements keep their order."""
    for i in range(1, len(a)):
        v = a[i]
        j = i
        while j > 0 and v < a[j - 1]:
            a[j] = a[j - 1]
            j -= 1
        a[j] = v
    return a


if __name__ == "__main__":
    data = [29, 10, 14, 37, 13, 5, 41, 22]
    print("Sorted:", insertion_sort(data))
Sorted: [5, 10, 13, 14, 22, 29, 37, 41]A pure-Python insertion sort is useful for learning and slow in practice. The standard library’s bisect.insort() does the binary-search insertion for you, and sorted() is the right call for sorting a whole list.
C#
// InsertionSort.cs - insertion sort in C#
namespace MyCPlus.Sorting;

public static class InsertionSort
{
    // Stable, in place.
    public static void Sort(int[] a)
    {
        for (int i = 1; i < a.Length; i++)
        {
            int v = a[i];
            int j = i;
            while (j > 0 && v < a[j - 1])
            {
                a[j] = a[j - 1];
                j--;
            }
            a[j] = v;
        }
    }
}
// Program.cs - sorts the article's array with InsertionSort.Sort
using System;
namespace MyCPlus.Sorting;
public static class Program
{
public static void Main()
{
int[] data = { 29, 10, 14, 37, 13, 5, 41, 22 };
InsertionSort.Sort(data);
Console.WriteLine("Sorted: [" + string.Join(", ", data) + "]");
}
}Sorted: [5, 10, 13, 14, 22, 29, 37, 41]When to Use Insertion Sort
| Situation | Use insertion sort? | Why |
|---|---|---|
| Small arrays, a few dozen elements | Yes | Faster than qsort() up to 256 elements in the measurements above |
| Every element close to its final position | Yes | Cost is O(nk) for displacement k |
| Adding a few items to an already sorted array | Yes | Each insertion costs only its own displacement |
| A few elements far out of place | No | Each one pays its full distance: 810,213 moves for 100 swaps |
| Large random arrays | No | 25 million moves at n = 10,000; use the library sort |
| Stability needed in library code | Use std::stable_sort or the language’s stable sort | Same guarantee, O(n log n) |
Key Takeaways
- Insertion sort moves an element once per inversion. On five inputs of 10,000 values, moves equaled the independently counted inversions exactly, from 0 to 49,994,942.
- “Nearly sorted” means small displacement. Locally shuffled data cost 27,735 comparisons; 100 far swaps cost 820,212.
- Binary insertion sort cuts comparisons, not moves. It made about 120,000 comparisons on every input and ran about 6.5 times faster at 20,000 elements, but it is still O(n²).
- Insertion sort beat
qsort()on small arrays. It was about 2.5 times faster per element at 16 elements and stayed ahead up to 256 on this machine, which is why libstdc++, OpenJDK and CPython all use it for small ranges. - Keep the index from going below zero.
size_t jwithj >= 0loops forever; one GCC build printed correct output three runs in a row while a Clang build printed garbage. - Keep the comparison strict.
<=still sorts but reverses equal keys.
Frequently Asked Questions
Conclusion
Insertion sort is usually filed under “simple and slow”, and both halves are true for large random input. What makes it worth understanding is that its cost has an exact description: one move per inversion, plus at most one comparison per element. That turns vague advice about “nearly sorted data” into something you can check, and it explains why an algorithm that loses badly at 20,000 elements is still inside the sort functions of three major standard libraries.
The natural next step is the algorithm that fixes insertion sort’s weakness for far-away elements by moving them long distances first: Shell sort, which is insertion sort run over shrinking gaps.
Source Code and Tests
The C code is in mycplus/c-examples/sorting/insertion-sort  and the C++ code in mycplus/cpp-examples/sorting/insertion-sort
 . The Java, Python and C# versions are in mycplus/java-examples/sorting/insertion-sort, mycplus/python-examples/sorting/insertion-sort and mycplus/csharp-examples/sorting/insertion-sort, each with its own tests and workflow.
cmake -S . -B build
cmake --build build
ctest --test-dir build --output-on-failure
What the builds check on each change:
- Compilation with warnings as errors: GCC and Clang with
-Wall -Wextra -pedantic -Werror(C11 and C17; C++17 and C++20), and MSVC with/W4 /WX. - Correctness against a reference: both C functions against
qsort()on 20,000 random arrays of 0 to 64 elements, including empty arrays,INT_MIN,INT_MAXand heavy duplication; both C++ templates againststd::stable_sorton 5,000 inputs instd::vectorandstd::list, which checks stability as well as order. - The output on this page: the example, the trace, the inversion table, the stability pitfall and the C++ demo are compared with the output blocks above.
- Sanitizers: all tests run again under AddressSanitizer and UndefinedBehaviorSanitizer.
- The pitfalls: the build confirms that GCC warns about the unsigned index and the unsequenced expression, and that AddressSanitizer reports the out-of-bounds read.
The builds do not run the timing program, because timings depend on the machine. A green badge means the code compiles on those toolchains and passes those tests; it does not reproduce the timings above.