
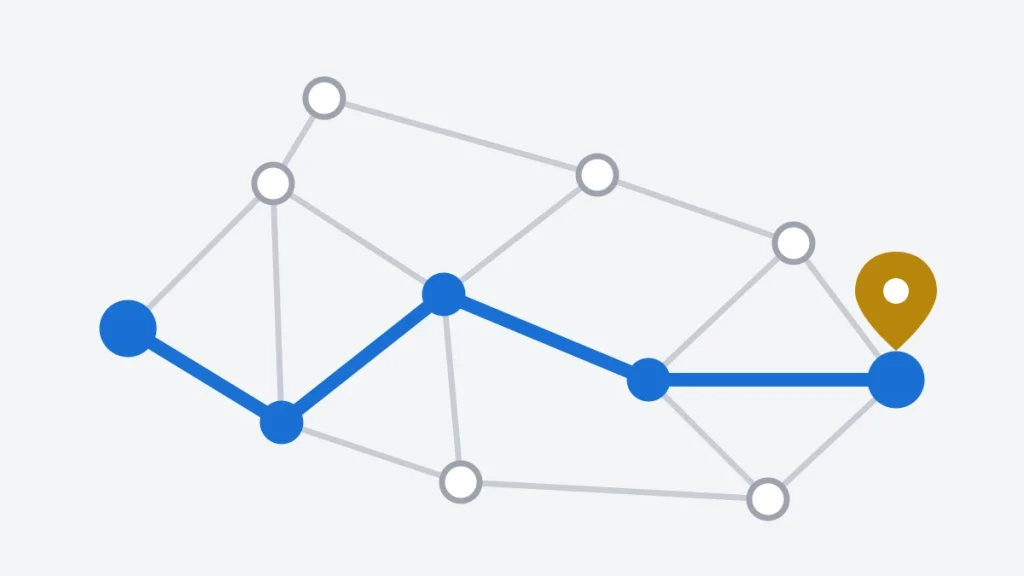
On the map in this article, a direct road runs 240 km from Ashford to Fairhaven, but the shortest route between them is 216 km, through Corwen and Elmstead. A shortest-path algorithm finds detours like that one without trying every possible route. That matters, because the number of routes grows faster than exponentially with the size of the map.
This tutorial builds a small route planner in C that reads a road map from a text file and answers two kinds of question. Dijkstra’s algorithm answers “how far is every town from here?” and Floyd–Warshall answers “how far is every town from every other town?”. You will see both work step by step, rebuild the actual route rather than just its length, and handle towns that no road reaches. You will also see what negative distances do to each algorithm, and a benchmark that shows when each one is faster. All the code is tested on Linux and Windows, and a C++17 version of the planner is in the same repository.
What Is the Shortest Path Problem?
The shortest path problem asks for the route between two points in a weighted graph whose edge weights add up to the smallest total. The points are nodes (towns, routers, game tiles), the connections are edges (roads, cables, moves), and each edge has a weight (kilometres, milliseconds, cost). The shortest route is not always the one with the fewest edges: Ashford to Fairhaven takes two roads instead of one and still comes out 24 km shorter.
The problem comes in two main forms:
- Single-source: the shortest distance from one starting node to every other node. Dijkstra’s algorithm solves this when no weight is negative.
- All-pairs: the shortest distance between every pair of nodes, as a table. Floyd–Warshall solves this in one run, and it also copes with negative weights.
| Algorithm | Answers | Negative weights | Time | Best for |
|---|---|---|---|---|
| Breadth-first search | One source, fewest edges | Weights not used | O(V + E) | Unweighted graphs |
| Dijkstra (binary heap) | One source | Not allowed | O((V + E) log V) | Road maps, networks, most real graphs |
| Bellman–Ford | One source | Allowed; detects negative cycles | O(V × E) | Negative weights, distance-vector routing |
| Floyd–Warshall | Every pair | Allowed; detects negative cycles | O(V³) | Small or dense graphs, full distance tables |
| A* | One source, one target | Not allowed | Depends on the heuristic | Game maps and GPS, where a good distance estimate exists |
V is the number of nodes and E the number of edges. The rest of this article implements the two rows in the middle: Dijkstra and Floyd–Warshall. Bellman–Ford appears too, as the slow but simple reference that the tests check both of them against.
Where shortest paths are used
- Navigation. A route planner treats junctions as nodes and road segments as edges, weighted by distance or by expected travel time.
- Network routing. Routers running OSPF build their routing tables with Dijkstra’s algorithm. RFC 2328, the OSPF specification, says so in its section 16.1: “Using the Dijkstra algorithm, a tree is formed from this subset of the link state database.”
- Logistics. A depot that dispatches vans to every customer needs the full table of distances between stops before it can plan any tour. That is an all-pairs problem.
- Games. Pathfinding for units on a map is shortest paths on a grid, usually with A*, which is Dijkstra’s algorithm guided by an estimate of the remaining distance.
- Finance. If the weight of each currency exchange is the negative logarithm of its rate, a negative cycle in the graph is a sequence of trades that ends with more money than it started with.
The Example Map
The planner reads maps from plain text files with one road per line: two town names and a whole-number distance in kilometres. Every road runs both ways. Blank lines and lines starting with # are ignored.
# Lakeland road map: town,town,kilometres (every road runs both ways)
Ashford,Bramley,45
Ashford,Corwen,62
Ashford,Fairhaven,240
Bramley,Corwen,30
Bramley,Dunmore,74
Corwen,Dunmore,51
Corwen,Elmstead,88
Dunmore,Elmstead,40
Dunmore,Glenrock,97
Elmstead,Fairhaven,66
Elmstead,Harlow Bay,120
Fairhaven,Harlow Bay,58
Glenrock,Harlow Bay,83
Glenrock,Ironbridge,64
Harlow Bay,Juniper,101
Ironbridge,Juniper,49
Ironbridge,Larkspur,92
Juniper,Larkspur,37

# An island with its own ferry road, not connected to the mainland
Kestrel Point,Seal Rock,12The map is fictional and small enough to check by hand, but it has the features that break naive code. The 240 km road from Ashford to Fairhaven is longer than a detour. Some pairs of towns are joined by several routes of similar length. And Kestrel Point and Seal Rock are on an island with no road to the mainland, so some questions have no answer at all.
Representing the Graph in C
A graph needs a way to answer “which roads leave this town, and how long is each one?”. There are two standard representations:
- An adjacency matrix is a V × V table where cell (u, v) holds the length of the road from u to v. It uses V² cells however few roads there are.
- Adjacency lists give each node an array of its outgoing edges. They use memory in proportion to the number of edges, which suits road maps, where each town connects to only a handful of others.
The planner stores the map as adjacency lists, and Floyd–Warshall builds its own matrix from them because it needs a full table anyway.
#ifndef GRAPH_H
#define GRAPH_H

#include <limits.h>
#include <stdbool.h>
#include <stddef.h>
#include <stdio.h>

/* Distances are 64-bit, and "no path" is a separate value that is never added to. */
typedef long long dist_t;
#define DIST_INF LLONG_MAX

typedef struct {
    int to;
    dist_t weight;
} edge;

/* A weighted directed graph stored as adjacency lists. An undirected road is
   two edges, one in each direction. Nodes have names, so maps can use towns. */
typedef struct {
    int n;               /* number of nodes */
    int cap;
    char **names;
    edge **adj;          /* adj[u][0 .. deg[u]-1] are the edges leaving u */
    int *deg;
    int *adj_cap;
} graph;

void graph_init(graph *g);
void graph_free(graph *g);

/* Returns the node's index, adding it if the name is new; -1 if out of memory. */
int graph_add_node(graph *g, const char *name);
/* Returns the node's index, or -1 if there is no node with that name. */
int graph_find(const graph *g, const char *name);
bool graph_add_edge(graph *g, int from, int to, dist_t weight);

/* Reads "Town A,Town B,distance" lines (undirected roads). Blank lines and
   lines starting with '#' are skipped. On error, fills err with the line
   number and the reason, and returns false. */
bool graph_load_map(graph *g, FILE *in, char *err, size_t err_len);

#endif
Three decisions in this header prevent bugs that are otherwise easy to write.
Distances are 64-bit. A long long holds totals up to about 9.2 × 10¹⁸, so adding up even a billion roads of the largest allowed length cannot overflow.
“No path” is LLONG_MAX, and the code never adds anything to it. Every place that extends a path first checks that the distance it starts from is finite. A sentinel such as 9999 looks simpler but fails as soon as a real route is longer than it, which the mistakes section demonstrates.
Town names are mapped to indexes when the map loads. The algorithms then work with integers from 0 to n − 1. The loader numbers towns in the order they first appear, rejects roads from a town to itself, and reports the line number of any problem:
Output:
route: tests/bad_map.txt: line 3: needs two town names and a distance from 1 to 1000000000Dijkstra’s Algorithm
Dijkstra’s algorithm finds the shortest distance from one node to every other node by always finishing the closest unfinished node next. It keeps a tentative distance for every node, starting at 0 for the source and “infinity” for the rest. Then it repeats one step:
- Take the unfinished node with the smallest tentative distance, and mark it finished (settled). Its distance is now final.
- For each road leaving it, check whether going through this node gives the neighbour a shorter distance than it has now. If it does, lower the neighbour’s distance and remember this node as the neighbour’s predecessor. This step is called relaxing the edge.
Settling the closest node is safe because every other route to it must pass through some node that is at least as far away, and with non-negative road lengths that route cannot come out shorter. That argument is also exactly why Dijkstra’s algorithm fails when a weight is negative.
A binary heap picks the closest node
Scanning every node to find the closest one costs O(V) per step and O(V²) in total. A binary min-heap returns the smallest distance in O(log V) instead. The heap sort article explains how a heap lives in an array; this one stores (distance, node) pairs:
/* A min-heap of (distance, node) pairs. A node may be pushed more than once;
   stale entries are skipped when popped ("lazy deletion"). */
typedef struct {
    dist_t d;
    int node;
} heap_item;

typedef struct {
    heap_item *items;
    size_t len, cap;
} heap;
static bool heap_push(heap *h, dist_t d, int node)
{
if (h->len == h->cap) {
size_t cap = h->cap ? h->cap * 2 : 16;
heap_item *bigger = realloc(h->items, cap * sizeof *bigger);
if (bigger == NULL)
return false;
h->items = bigger;
h->cap = cap;
}
size_t i = h->len++;
while (i > 0 && h->items[(i - 1) / 2].d > d) { /* sift up */
h->items[i] = h->items[(i - 1) / 2];
i = (i - 1) / 2;
}
h->items[i].d = d;
h->items[i].node = node;
return true;
}static heap_item heap_pop(heap *h)
{
heap_item top = h->items[0], last = h->items[--h->len];
size_t i = 0;
for (;;) { /* sift down */
size_t child = 2 * i + 1;
if (child >= h->len)
break;
if (child + 1 < h->len && h->items[child + 1].d < h->items[child].d)
child++;
if (h->items[child].d >= last.d)
break;
h->items[i] = h->items[child];
i = child;
}
if (h->len > 0)
h->items[i] = last;
return top;
}C’s standard library has no priority queue that can lower the priority of an item already inside it. So when a node’s distance improves, the code simply pushes the node again with its new distance. The old entry stays in the heap, and when it is eventually popped, its distance is larger than the node’s current one, so it is skipped. This technique is called lazy deletion. It costs some extra heap entries, at most one per edge, and keeps the code short.
bool dijkstra_trace(const graph *g, int source, dist_t *dist, int *prev, FILE *trace)
{
    for (int u = 0; u < g->n; u++)
        for (int k = 0; k < g->deg[u]; k++)
            if (g->adj[u][k].weight < 0)
                return false;

    for (int v = 0; v < g->n; v++) {
        dist[v] = DIST_INF;
        prev[v] = -1;
    }
    dist[source] = 0;

    heap h = {NULL, 0, 0};
    bool ok = heap_push(&h, 0, source);
    while (ok && h.len > 0) {
        heap_item top = heap_pop(&h);
        if (top.d > dist[top.node])
            continue;                                   /* a stale entry */
        int u = top.node;
        if (trace)
            fprintf(trace, "settle %-12s at %lld\n", g->names[u], top.d);
        for (int k = 0; k < g->deg[u]; k++) {
            const edge *e = &g->adj[u][k];
            dist_t candidate = dist[u] + e->weight;
            if (candidate < dist[e->to]) {
                dist[e->to] = candidate;
                prev[e->to] = u;
                if (trace)
                    fprintf(trace, "    %-12s %lld via %s\n", g->names[e->to], candidate, g->names[u]);
                ok = heap_push(&h, candidate, e->to);
                if (!ok)
                    break;
            }
        }
    }
    free(h.items);
    return ok;
}
The function refuses to run when any edge is negative instead of returning wrong answers. The trace parameter is for the walkthrough below; the plain dijkstra() function calls this one with NULL.
Watching Dijkstra’s algorithm work
The trace program prints each town as it is settled, and each improvement that follows. Here it is from Ashford:
Output:
settle Ashford      at 0
    Bramley      45 via Ashford
    Corwen       62 via Ashford
    Fairhaven    240 via Ashford
settle Bramley      at 45
    Dunmore      119 via Bramley
settle Corwen       at 62
    Dunmore      113 via Corwen
    Elmstead     150 via Corwen
settle Dunmore      at 113
    Glenrock     210 via Dunmore
settle Elmstead     at 150
    Fairhaven    216 via Elmstead
    Harlow Bay   270 via Elmstead
settle Glenrock     at 210
    Ironbridge   274 via Glenrock
settle Fairhaven    at 216
settle Harlow Bay   at 270
    Juniper      371 via Harlow Bay
settle Ironbridge   at 274
    Juniper      323 via Ironbridge
    Larkspur     366 via Ironbridge
settle Juniper      at 323
    Larkspur     360 via Juniper
settle Larkspur     at 360
Two lines in this output show the algorithm correcting itself:
- Dunmore first gets 119 km through Bramley (45 + 74). When Corwen is settled one step later, the route through Corwen gives 113 km (62 + 51), and the distance drops. The 119 entry stays in the heap as a stale entry and is skipped when it comes up.
- Fairhaven gets 240 km from the direct road as soon as Ashford is settled, and it keeps that distance until Elmstead is settled at 150 km. Then 150 + 66 = 216 replaces it. Fairhaven is settled only after that, which is why its final distance is the detour, not the direct road.
Each town is settled exactly once, in order of distance: 0, 45, 62, 113, 150, 210, 216 and so on. The island towns never appear, because no road from the mainland reaches them.
Rebuilding the route
Distances alone do not tell a driver which roads to take. The prev array does: prev[v] is the town before v on its shortest route. Following it backwards from the destination reaches the source, and reversing that list gives the route in driving order:
int path_from_prev(const int *prev, int source, int target, int *out, int cap)
{
    int len = 0;
    for (int v = target; v != -1; v = prev[v]) {
        if (len == cap)
            return 0;
        out[len++] = v;
    }
    if (out[len - 1] != source)
        return 0;                                       /* the chain never reached the source */
    for (int i = 0, j = len - 1; i < j; i++, j--) {     /* it was built backwards */
        int t = out[i];
        out[i] = out[j];
        out[j] = t;
    }
    return len;
}
The route planner prints the result as a table of legs:
Output:
Ashford to Larkspur (Dijkstra)

  From           To             Road km  Total km
  Ashford        Corwen              62        62
  Corwen         Dunmore             51       113
  Dunmore        Glenrock            97       210
  Glenrock       Ironbridge          64       274
  Ironbridge     Juniper             49       323
  Juniper        Larkspur            37       360

Total: 360 km over 6 roads
This is the blue route in Figure 1. The --from option prints the whole single-source result instead: every town’s distance from Ashford and the town it is reached through.
Output:
Distances from Ashford (Dijkstra)

  Ashford            0 km  via -
  Bramley           45 km  via Ashford
  Corwen            62 km  via Ashford
  Fairhaven        216 km  via Elmstead
  Dunmore          113 km  via Corwen
  Elmstead         150 km  via Corwen
  Glenrock         210 km  via Dunmore
  Harlow Bay       270 km  via Elmstead
  Ironbridge       274 km  via Glenrock
  Juniper          323 km  via Ironbridge
  Larkspur         360 km  via Juniper
  Kestrel Point  no route
Seal Rock no routeThe Floyd–Warshall Algorithm
Floyd–Warshall computes the shortest distance between every pair of nodes by allowing one more possible stop at a time. It starts with a table that holds only the direct roads. Then, for each node k in turn, it asks of every pair (i, j): is going from i to k and then from k to j shorter than the best route found so far?
dist[i][j] = min(dist[i][j], dist[i][k] + dist[k][j])After round k, dist[i][j] is the shortest route from i to j whose intermediate stops are all among nodes 0 to k. After the last round every node is allowed as a stop, so the table is complete. This is dynamic programming: each round builds on the finished results of the previous one, just as the longest common subsequence table builds on smaller prefixes.
To rebuild routes, the algorithm keeps a second table, next, where next[i][j] is the first town after i on the best route to j. When a route through k wins, the first step towards j becomes the first step towards k.
bool floyd_warshall_trace(const graph *g, dist_t *dist, int *next, FILE *trace)
{
    const int n = g->n;
    for (int i = 0; i < n; i++)
        for (int j = 0; j < n; j++) {
            dist[i * n + j] = i == j ? 0 : DIST_INF;
            next[i * n + j] = i == j ? i : -1;
        }
    for (int u = 0; u < n; u++)
        for (int k = 0; k < g->deg[u]; k++) {
            const edge *e = &g->adj[u][k];
            if (e->weight < dist[u * n + e->to]) {      /* keep the shortest parallel road */
                dist[u * n + e->to] = e->weight;
                next[u * n + e->to] = e->to;
            }
        }

    if (trace) {
        fprintf(trace, "Start: direct roads only\n");
        print_matrix(g, dist, trace);
    }
    for (int k = 0; k < n; k++) {
        for (int i = 0; i < n; i++) {
            if (dist[i * n + k] == DIST_INF)
                continue;                               /* never add to "infinity" */
            for (int j = 0; j < n; j++) {
                if (dist[k * n + j] == DIST_INF)
                    continue;
                dist_t through_k = dist[i * n + k] + dist[k * n + j];
                if (through_k < dist[i * n + j]) {
                    dist[i * n + j] = through_k;
                    next[i * n + j] = next[i * n + k];
                }
            }
        }
        if (trace) {
            fprintf(trace, "\nAfter allowing stops at %s (k = %d)\n", g->names[k], k);
            print_matrix(g, dist, trace);
        }
        /* A town that can reach itself at negative cost lies on a negative cycle.
           Stop now: every further round would push the totals further down,
           doubling them, until they overflow. */
        for (int i = 0; i < n; i++)
            if (dist[i * n + i] < 0)
                return false;
    }
    return true;
}
Both tables are single malloc blocks of n × n cells, indexed as i * n + j (row-major order, the same layout C uses for two-dimensional arrays). Two details matter:
- Skipping “infinity”. If either half of the route through k does not exist, the code moves on before adding anything. Without that check,
LLONG_MAX + 5overflows, which is undefined behavior in C. - Stopping at a negative cycle. That check is explained in the section on negative distances.
Watching Floyd–Warshall fill the table
The full Lakeland table has 169 cells, so the trace uses a four-town map instead: Ashford, Bramley, Corwen and Dunmore, with the same roads between them as in Lakeland.
Output:
Start: direct roads only
           Ashford Bramley  Corwen Dunmore
Ashford          0      45      62       -
Bramley         45       0      30      74
Corwen          62      30       0      51
Dunmore          -      74      51       0

After allowing stops at Ashford (k = 0)
           Ashford Bramley  Corwen Dunmore
Ashford          0      45      62       -
Bramley         45       0      30      74
Corwen          62      30       0      51
Dunmore          -      74      51       0

After allowing stops at Bramley (k = 1)
           Ashford Bramley  Corwen Dunmore
Ashford          0      45      62     119
Bramley         45       0      30      74
Corwen          62      30       0      51
Dunmore        119      74      51       0

After allowing stops at Corwen (k = 2)
           Ashford Bramley  Corwen Dunmore
Ashford          0      45      62     113
Bramley         45       0      30      74
Corwen          62      30       0      51
Dunmore        113      74      51       0

After allowing stops at Dunmore (k = 3)
           Ashford Bramley  Corwen Dunmore
Ashford          0      45      62     113
Bramley         45       0      30      74
Corwen          62      30       0      51
Dunmore        113      74      51       0
Follow the Ashford–Dunmore cell. There is no direct road, so it starts at -. Allowing stops at Bramley gives 45 + 74 = 119. Allowing stops at Corwen as well gives 62 + 51 = 113, which wins. The rounds for Ashford and Dunmore change nothing, because no shorter route passes through either of them. On this map, Dijkstra’s algorithm found the same two values in the same order.
Rebuilding a route from the next table
With the next table, a route is rebuilt forwards: start at i and keep stepping to next[current][j] until you arrive at j.
int path_from_next(const int *next, int n, int source, int target, int *out, int cap)
{
    if (next[source * n + target] == -1)
        return 0;
    int len = 0;
    for (int v = source; ; v = next[v * n + target]) {
        if (len == cap)
            return 0;
        out[len++] = v;
        if (v == target)
            return len;
    }
}
The planner takes floyd as a fourth argument. Here it plans the trip back:
Output:
Larkspur to Ashford (Floyd-Warshall)

  From           To             Road km  Total km
  Larkspur       Juniper             37        37
  Juniper        Ironbridge          49        86
  Ironbridge     Glenrock            64       150
  Glenrock       Dunmore             97       247
  Dunmore        Corwen              51       298
  Corwen         Ashford             62       360

Total: 360 km over 6 roads
The same 360 km over the same roads, in reverse. The tests check that the two algorithms agree on every pair of towns.
The all-pairs distance table
Floyd–Warshall’s real product is the whole table, which --table prints with town names cut to four letters:
Output:
km      Ashf  Bram  Corw  Fair  Dunm  Elms  Glen  Harl  Iron  Juni  Lark  Kest  Seal
Ashf       0    45    62   216   113   150   210   270   274   323   360     -     -
Bram      45     0    30   180    74   114   171   234   235   284   321     -     -
Corw      62    30     0   154    51    88   148   208   212   261   298     -     -
Fair     216   180   154     0   106    66   141    58   205   159   196     -     -
Dunm     113    74    51   106     0    40    97   160   161   210   247     -     -
Elms     150   114    88    66    40     0   137   120   201   221   258     -     -
Glen     210   171   148   141    97   137     0    83    64   113   150     -     -
Harl     270   234   208    58   160   120    83     0   147   101   138     -     -
Iron     274   235   212   205   161   201    64   147     0    49    86     -     -
Juni     323   284   261   159   210   221   113   101    49     0    37     -     -
Lark     360   321   298   196   247   258   150   138    86    37     0     -     -
Kest       -     -     -     -     -     -     -     -     -     -     -     0    12
Seal       -     -     -     -     -     -     -     -     -     -     -    12     0
A table like this is what a delivery company needs before it plans the order of a van’s stops. The table is symmetric because every road runs both ways, and the island’s two rows are empty except for each other.
When No Route Exists
Asking for a route to an island town must give a clear answer, not a crash or a distance of 9.2 × 10¹⁸ km:
Output:
No route from Ashford to Seal Rock: no chain of roads connects them.The planner exits with status 1 here. It uses 0 for a route found and 2 for bad input such as an unknown town, so a script can tell “no route” apart from “you mistyped the town”.
Inside the code, an unreachable town is recognized in two ways, and both are needed:
- Its distance is still
DIST_INF, because no relaxation ever reached it. - Rebuilding its route fails.
prevends at −1 before reaching the source, ornext[source][target]is −1.path_from_prev()checks that the chain really ends at the source, andpath_from_next()checks for −1 before taking its first step. One of the tests removes that check frompath_from_next(), and AddressSanitizer then reports a heap-buffer-overflow, because the loop indexes the table with −1.
Negative Distances
Road lengths are never negative, but other weights can be. An electric delivery van’s planner might measure each road in watt-hours of battery used, and going downhill, regenerative braking puts energy back. That road has a negative cost, and the roads become one-way, because the climb back up costs more.
Dijkstra’s algorithm gives wrong answers with negative edges
pitfalls/negative_edge.c runs the textbook version of Dijkstra’s algorithm, which settles each place once and never looks back, on a four-place map with one downhill road, and compares it with Bellman–Ford:
Output:
Place      Dijkstra  Bellman-Ford
Depot          0 Wh          0 Wh
Ridge        800 Wh        800 Wh
Valley       500 Wh        400 Wh   <- wrong
Town         800 Wh        700 Wh   <- wrong
The textbook algorithm settles Valley at 500 Wh because it is the closest unsettled place at that moment. The 400 Wh route through Ridge (800 Wh up, then 400 Wh back on the way down) is found only after Valley is final, and Town inherits the error. Nothing crashes, and every number looks plausible. That is why the library’s dijkstra() returns false when it sees a negative weight instead of trying.
Floyd–Warshall handles negative edges
Floyd–Warshall never declares a distance final until the last round, so negative edges do not break it. One of the tests builds the same van map and checks that Floyd–Warshall finds 700 Wh to Town through Ridge and Valley. Over thousands of random graphs with negative edges, it agrees with Bellman–Ford on every pair.
Negative cycles have no shortest path
If a loop of roads adds up to less than zero, going round it once more always makes the route shorter, so no shortest route exists. In the currency example, that loop is an arbitrage opportunity. Floyd–Warshall detects one when a node’s distance to itself, dist[i][i], drops below zero.
The check must run after every round, not once at the end. During testing, the first version of this code checked only at the end, and on random graphs with negative cycles UndefinedBehaviorSanitizer stopped it with:
runtime error: signed integer overflow: -6316354008743586593 + -6316354008743590066 cannot be represented in type 'long long int'Once a negative cycle exists, each round can roughly double the size of the negative totals, and 64 bits do not last long. Stopping in the first round where any dist[i][i] is negative avoids that, because until then every value in the table is the length of a route that repeats no town, which cannot exceed (n − 1) times the longest road. The tests include this exact mistake, and UBSan catches it every time.
Dijkstra vs Floyd–Warshall: When Each Wins
If you only need routes from one place, use Dijkstra’s algorithm: from Ashford it does one pass over the map, while Floyd–Warshall computes all 169 entries. The interesting question is the all-pairs case, where you can either run Dijkstra once from every node or run Floyd–Warshall once.
On paper, Dijkstra from every node costs O(V × (V + E) log V) and Floyd–Warshall costs O(V³). On a road map, E grows like V, so Dijkstra’s total is about V² log V, which should win. On a dense graph, where E is close to V², Dijkstra’s total becomes V³ log V, and Floyd–Warshall should win. bench/timing.c measures both cases.
How this was measured
| Setting | Value |
|---|---|
| Date | November 17, 2026 |
| Machine | Intel Core i7-8700K desktop (6 cores, 12 threads), Windows 11 Education |
| Environment | WSL 2, Ubuntu 24.04.5; GCC 13.3, CMake Release build (-O3 -DNDEBUG), C11 |
| Threads | One; both algorithms are single-threaded |
| Graphs | Sparse: a ring plus one random road per node, both directions, so about 4 directed edges per node. Dense: every ordered pair connected. Weights 1 to 1,000. Same seed every run |
| Sizes | 100, 200, 400, 800 and 1,600 nodes |
| Dijkstra | Binary heap with lazy deletion, run once from every node; “one source” is that total divided by the number of nodes |
| Floyd–Warshall | One run, filling the distance and next-hop tables |
| Runs | 5 per size; the median is reported |
| Check | The sum of all finite distances must match between the two methods before a row is printed |
The table reports medians only: no percentiles, no CPU pinning and no control of frequency scaling. Both methods run on the same graph in the same process, and their checksums must match before anything is printed. The timings measure the algorithms alone, not reading a map file or printing routes.
Results
| Graph | Nodes | Directed edges | Dijkstra, one source (ms) | Dijkstra, every source (ms) | Floyd–Warshall (ms) | Faster for all pairs |
|---|---|---|---|---|---|---|
| sparse | 100 | 394 | 0.007 | 0.74 | 1.03 | Dijkstra, 1.4× |
| sparse | 200 | 800 | 0.017 | 3.32 | 7.83 | Dijkstra, 2.4× |
| sparse | 400 | 1,598 | 0.036 | 14.56 | 57.72 | Dijkstra, 4.0× |
| sparse | 800 | 3,196 | 0.080 | 63.75 | 492.09 | Dijkstra, 7.7× |
| sparse | 1,600 | 6,396 | 0.167 | 266.92 | 4,845 | Dijkstra, 18.2× |
| dense | 100 | 9,900 | 0.040 | 3.97 | 1.64 | Floyd–Warshall, 2.4× |
| dense | 200 | 39,800 | 0.129 | 25.74 | 12.08 | Floyd–Warshall, 2.1× |
| dense | 400 | 159,600 | 0.420 | 167.97 | 89.75 | Floyd–Warshall, 1.9× |
| dense | 800 | 639,200 | 1.899 | 1,519 | 701.70 | Floyd–Warshall, 2.2× |
| dense | 1,600 | 2,558,400 | 8.217 | 13,147 | 6,215 | Floyd–Warshall, 2.1× |
What the numbers show:
- On sparse graphs, Dijkstra’s lead grows with size: from 1.4× at 100 nodes to 18.2× at 1,600 nodes. That is the V² log V against V³ difference showing up as the graphs grow.
- On dense graphs, Floyd–Warshall wins at every size, by a nearly constant 1.9× to 2.4×. Both totals grow roughly as V³ here (Dijkstra’s extra log V factor changes little at these sizes), and Floyd–Warshall’s three plain loops over one array run faster than heap operations that jump around memory.
- For a single source, there is no contest. One Dijkstra run on the 1,600-node sparse graph took 0.167 ms; Floyd–Warshall took 4,845 ms to compute the same answer along with every other pair’s.
- The compiler changes the factors, not the verdict. On the same PC under Windows, the MSVC build (
/O2) put Dijkstra 22.6× ahead on the 1,600-node sparse graph and Floyd–Warshall 3.0× to 3.5× ahead on dense graphs. The checksums were identical, so both builds computed the same distances. - Memory decides before time does. Floyd–Warshall’s two tables need 12 bytes per pair: about 31 MB at 1,600 nodes, and 120 GB at 100,000 nodes, a modest road network. Dijkstra needs memory only in proportion to the map.
Which algorithm to use
| Situation | Use | Why |
|---|---|---|
| Routes from one place, weights not negative | Dijkstra | One pass over the map; on the 1,600-node sparse graph it took under a millisecond |
| One route between two places on a big map | Dijkstra, stopping when the target is settled, or A* | No need to finish the rest of the map |
| Every pair, sparse graph (road and computer networks) | Dijkstra from every node | Wins by a growing margin as the graph grows |
| Every pair, dense graph or a few hundred nodes | Floyd–Warshall | Faster here, and shorter code |
| Negative weights, one source | Bellman–Ford | Dijkstra’s answers would be wrong |
| Negative weights, every pair | Floyd–Warshall, checking dist[i][i] after every round | Handles negative edges and reports negative cycles |
| Millions of nodes | Dijkstra or A* only | Floyd–Warshall’s V² table does not fit in memory |
Common Mistakes
Three of these are deliberately broken programs in the repository’s pitfalls/ directory. The other two came from the mutation tests described later, which put mistakes into the library on purpose.
1. Using an ordinary number to mean “no road”
Writing 9999, or INT_MAX, for a missing road looks harmless. pitfalls/magic_infinity.c runs Floyd–Warshall on a freight map of real lane lengths from Rotterdam to Vladivostok, first with 9999 meaning “no road” and then with a value no real total can reach:
Output:
With 9999 meaning "no road":
  Rotterdam to Vladivostok: 9999  (reported as no route)
With a sentinel no real distance can reach:
  Rotterdam to Vladivostok: 11610 km
INT_MAX + 1200 in 32-bit two's complement: -2147482449
No single lane is longer than 9999 km, but the whole journey is 11,610 km. Any total over the sentinel cannot win against “no road”, so the program says the two cities are not connected. INT_MAX fails differently: adding a road length to it overflows, which is undefined behavior. On ordinary hardware the sum wraps to a large negative number, which then looks like the best route of all. The fix is the one this library uses: a sentinel no real distance can reach, never added to.
2. Putting the k loop of Floyd–Warshall on the inside
The three nested loops look interchangeable. They are not: k must be the outer loop.
for (int k = 0; k < N; k++)                         /* k outermost: correct */
    for (int i = 0; i < N; i++)
        for (int j = 0; j < N; j++)
            relax(right, i, k, j);
for (int i = 0; i < N; i++)                         /* k innermost: wrong */
    for (int j = 0; j < N; j++)
        for (int k = 0; k < N; k++)
            relax(wrong, i, k, j);
Output:
From      To          k outer   k inner
Ashford   Bramley         271  no route
Ashford   Corwen          241  no route
2 of 10 pairs wrong with k innermost
With k inside, the Ashford–Bramley cell is finished before Ashford–Corwen and Ashford–Dunmore, the pieces its route is made of, have been computed. Two routes on a five-town chain come out as “no route”, and nothing warns you.
3. Using Dijkstra’s algorithm with negative weights
The negative distances section shows the wrong answers it gives. Check the weights before running it, as dijkstra() does, or use Bellman–Ford.
4. Relaxing on equal distances
Changing candidate < dist[v] to candidate <= dist[v] looks like it only changes which of two equally short routes is kept. But a pair of towns joined by a zero-length road (two names for the same junction, for example) then pushes each other back into the heap forever. In the mutation tests, this one-character change made the test suite run until its 30-second timeout.
5. Trusting correct distances as proof of a correct heap
A heap that pops the largest child instead of the smallest still produces the right distances with lazy deletion. Towns get processed with a provisional distance, improved later and processed again, so the algorithm turns into a slower label-correcting search. Deleting the line that skips stale heap entries has the same effect. With either mistake in place, all 3.2 million distance and route checks passed. Only a test that checks each reachable town is settled exactly once caught them.
The C++ Version
The repository also has the planner in C++17 (cpp/route.cpp). It prints exactly the same output as the C program, and the test suite checks this byte for byte. The standard library removes most of the bookkeeping: std::vector replaces the hand-grown arrays, std::unordered_map maps names to indexes, and std::priority_queue with std::greater<> is the min-heap. The STL article shows this same std::greater trick turning a priority queue into a min-heap.
SingleSource dijkstra(const Graph& g, int source)
{
    SingleSource r{std::vector<Dist>(g.size(), kInf), std::vector<int>(g.size(), -1)};
    using Item = std::pair<Dist, int>;
    std::priority_queue<Item, std::vector<Item>, std::greater<>> queue;
    r.dist[source] = 0;
    queue.push({0, source});
    while (!queue.empty()) {
        auto [d, u] = queue.top();
        queue.pop();
        if (d > r.dist[u])
            continue;  // a stale entry
        for (const Edge& e : g.edges(u)) {
            if (d + e.weight < r.dist[e.to]) {
                r.dist[e.to] = d + e.weight;
                r.prev[e.to] = u;
                queue.push({r.dist[e.to], e.to});
            }
        }
    }
    return r;
}
Like the C version, std::priority_queue cannot lower an item’s priority, so it uses the same lazy deletion.
One bug appeared only in C++. The loader first added each road with g.add_road(g.add_node(a), g.add_node(b), km). C++ leaves the order in which function arguments are evaluated unspecified, and GCC evaluated the second add_node call first. Bramley therefore became town 0 instead of Ashford, and the --table output came out in a different order from the C program’s. The fix was to call add_node in two separate statements. The C loader does not have this problem, because it declares int u = graph_add_node(g, a), v = graph_add_node(g, b);, and the initializers in a declaration run in order.
How the Code Is Tested
A shortest-path function can return plausible numbers that are wrong, so the tests compare against an independent answer instead of a few hand-picked cases.
- Against Bellman–Ford on 4,000 random graphs. Bellman–Ford is slow, but its correctness argument is very simple: relax every edge V − 1 times. The test generates directed graphs with 1 to 30 nodes in four kinds: positive weights, weights including zero, negative weights without negative cycles, and weights that may form negative cycles. Floyd–Warshall must report a negative cycle exactly when Bellman–Ford finds one. Otherwise both algorithms must match Bellman–Ford on every pair, and Dijkstra must refuse exactly the graphs with a negative edge.
- Every route is walked. Each rebuilt route must start and end at the right towns, use only roads that exist, and add up to the reported distance.
- Settled once. Dijkstra’s trace must settle each reachable node exactly once, which catches heap mistakes that the distance checks cannot see.
- Byte-for-byte output. The route, table, trace and pitfall programs must print exactly what this article shows, in both C and C++.
- 13 deliberate mistakes.
tests/mutations.pyputs each mistake into a copy of the library, rebuilds the tests with AddressSanitizer and UndefinedBehaviorSanitizer, and confirms that they fail:
| Deliberate mistake | How the tests caught it |
|---|---|
| Dijkstra accepts negative weights | a check failed: !dijkstra(&g, 0, dist, prev) |
| Dijkstra does not skip stale heap entries | a check failed: settled[v] == (dist[v] != DIST_INF) |
| Dijkstra relaxes on equal distance (<=) | the tests did not finish in 30 s |
| heap pops the larger child | a check failed: settled[v] == (dist[v] != DIST_INF) |
| Floyd-Warshall keeps the last parallel road | a check failed: all[0 * 3 + 1] == 4 && all[0 * 3 + 2] == 4 |
| Floyd-Warshall adds to “infinity” | UBSan at shortest_path.c:151: signed integer overflow |
| Floyd-Warshall records the wrong next hop | a check failed: path_from_next(next, n, lark, a, path, n) == 7 && path[0] == lark && path[6] == a |
| negative-cycle test also fires on zero | a check failed: floyd_warshall(&g, all, next) |
| negative-cycle test only after the last round | UBSan at shortest_path.c:152: signed integer overflow |
| path from prev is not reversed | a check failed: path_adds_up(&g, path, len, s, t, bf[t]) |
| path from next ignores “no path” | AddressSanitizer: heap-buffer-overflow in path_from_next (shortest_path.c:194) |
| map loader accepts a zero distance | a check failed: !load_text(&g, text, err, sizeof err) |
| map loader adds roads one way only | a check failed: g.deg[1] == 2 |
| heap starts with room for 1 item, not 16 | passes (correctly: the change is harmless) |
The last line is a control: a change that should not matter (the heap’s starting size), which the tests correctly let through.
Key Takeaways
- Dijkstra’s algorithm settles the closest unfinished node first, so each node’s distance is final the moment it is settled. That only holds when no weight is negative.
- Floyd–Warshall allows one more possible stop per round and gives every pair’s distance in O(V³), with negative edges allowed.
- Store routes, not just distances. A
prevarray for Dijkstra and anexttable for Floyd–Warshall turn a distance into a list of roads. - Represent “no path” with a value that is never added to. A 9999 sentinel lost an 11,610 km route, and adding to
INT_MAXis undefined behavior. - Check for negative cycles after every round of Floyd–Warshall, or the totals overflow before the check is reached.
- Pick the algorithm by graph shape. On sparse graphs, Dijkstra from every node beat Floyd–Warshall 18.2× at 1,600 nodes; on dense graphs, Floyd–Warshall won by about 2×.
- Test against an independent algorithm. Bellman–Ford on thousands of random graphs, plus a settled-once check, caught every one of 13 deliberate mistakes.
Conclusion
Dijkstra’s algorithm and Floyd–Warshall answer different questions. Dijkstra’s algorithm is the tool for “how do I get there from here”, and it scales to maps with millions of nodes. Floyd–Warshall is the tool for “give me the whole distance table” on graphs of a few thousand nodes or fewer, and it is the simpler of the two to write correctly. Both need the same care at the edges: an unreachable town, a negative weight, and an “infinity” that must never be added to.
From here, A* adds a distance estimate to Dijkstra’s algorithm to find one route faster, and Bellman–Ford handles negative weights from a single source. For a graph algorithm that builds the cheapest network instead of the cheapest route, see Kruskal’s algorithm, and for more, the algorithms section.
Source Code and Tests

All programs on this page, the C++ version and the tests are in the graphs/shortest-path directory of the MYCPLUS C examples repository.
Build, test and run:
cmake -S . -B build
cmake --build build
ctest --test-dir build --output-on-failure
./build/route data/lakeland.txt Ashford Larkspur
To plan routes on your own map, write a file in the same Town A,Town B,distance format and pass it as the first argument.
What the build checks.
- Compilers: GCC and Clang under C11 and C17, plus C++17, with
-Wall -Wextra -pedantic -Werror, and MSVC under/W4 /WX. - Correctness: Dijkstra and Floyd–Warshall agree with Bellman–Ford on 4,000 random graphs, and every rebuilt route is checked road by road.
- Output: the C and C++ planners, the trace program and the pitfall programs print exactly the output shown here.
- Sanitizers: every test runs clean under AddressSanitizer and UndefinedBehaviorSanitizer, and the mutation tests confirm all 13 deliberate mistakes are caught.
The benchmark is built but not run by the tests, because timings depend on the machine.
What I Verified
Everything in the Ubuntu column was run for this article on Ubuntu 24.04 (x86-64, GCC 13.3, Clang 18, CMake 3.28, MinGW-w64 GCC 13). The WSL and Windows columns come from the run_all.sh and run_all.ps1 scripts in the repository, run on a desktop PC with an Intel Core i7-8700K.
| Check | Ubuntu 24.04 | WSL (Ubuntu) | Windows 11 |
|---|---|---|---|
Builds with warnings as errors: GCC and Clang (C11, C17, C++17) on Linux, MSVC /W4 /WX on Windows | GCC and Clang, C11 and C17: passed, zero warnings | GCC 13.3 and Clang, C11 and C17: passed, zero warnings | MSVC /W4 /WX, C11 and C17: built |
| 20 CTest tests: 4,000 random graphs against Bellman–Ford, and byte-for-byte outputs of the C and C++ planners, traces and pitfalls | 20 of 20 in all four configurations | 20 of 20 in all four configurations | 20 of 20 in C11 and in C17 |
| AddressSanitizer and UndefinedBehaviorSanitizer, every test | 20 of 20, clean | 20 of 20, clean | Not applicable |
| Valgrind memcheck: the test suite and both route programs | No errors, no leaks | No errors, no leaks | Not applicable |
| C and C++ planners compared on 355 command lines | Identical output | Covered by the CTest output checks | Covered by the CTest output checks |
| Windows build cross-compiled with MinGW-w64, warnings as errors | Passed | Not run | Not applicable |
| 13 deliberate mistakes injected into the library | 13 of 13 caught; the 1 harmless change passed | 13 of 13 caught; the 1 harmless change passed | Not run |
| Timing benchmark, 100 to 1,600 nodes (checksums identical in all three environments) | Run as a cross-check only (2-CPU container); not used in the article | Used for the table and Figure 2 | Same conclusions (MSVC /O2): Dijkstra 22.6× faster on the 1,600-node sparse graph, Floyd–Warshall 3.0× to 3.5× faster on dense graphs |
Not covered: macOS, 32-bit builds, graphs larger than 1,600 nodes, and A* or Bellman–Ford as tuned implementations (Bellman–Ford here is a test reference only).